The Inevitability of Failure
Traditional IT operated under a delusion: that with enough planning, testing, and expensive hardware, systems could achieve 100% uptime. Modern Cloud Operations (SRE) operates under a different reality: complex systems will inevitably fail. An AWS region will experience a power outage. A third-party API will push a bad update. A seemingly innocuous code commit will trigger an unhandled exception that cascades through the microservice architecture.
Because failure is inevitable, the maturity of an engineering organization is not judged by the absence of outages. It is judged by how the organization responds to outages, mitigates the customer impact, and learns from the event to prevent recurrence.
This guide explores the mechanics of modern cloud incident management, shifting the focus from "preventing all failures" to "recovering brilliantly," and establishing the cultural prerequisites for continuous improvement.
Metrics that Matter: MTTR and MTTD
Incident management focuses on reducing time. Two metrics dominate the discipline:
Mean Time to Detect (MTTD): How long does it take the organization to realize there is a problem? If a database cluster fails over, but the observability platform doesn't trigger an alert for 45 minutes, the MTTD is fatally high. Reducing MTTD requires aggressively tuning APM alerts and synthetic monitoring.
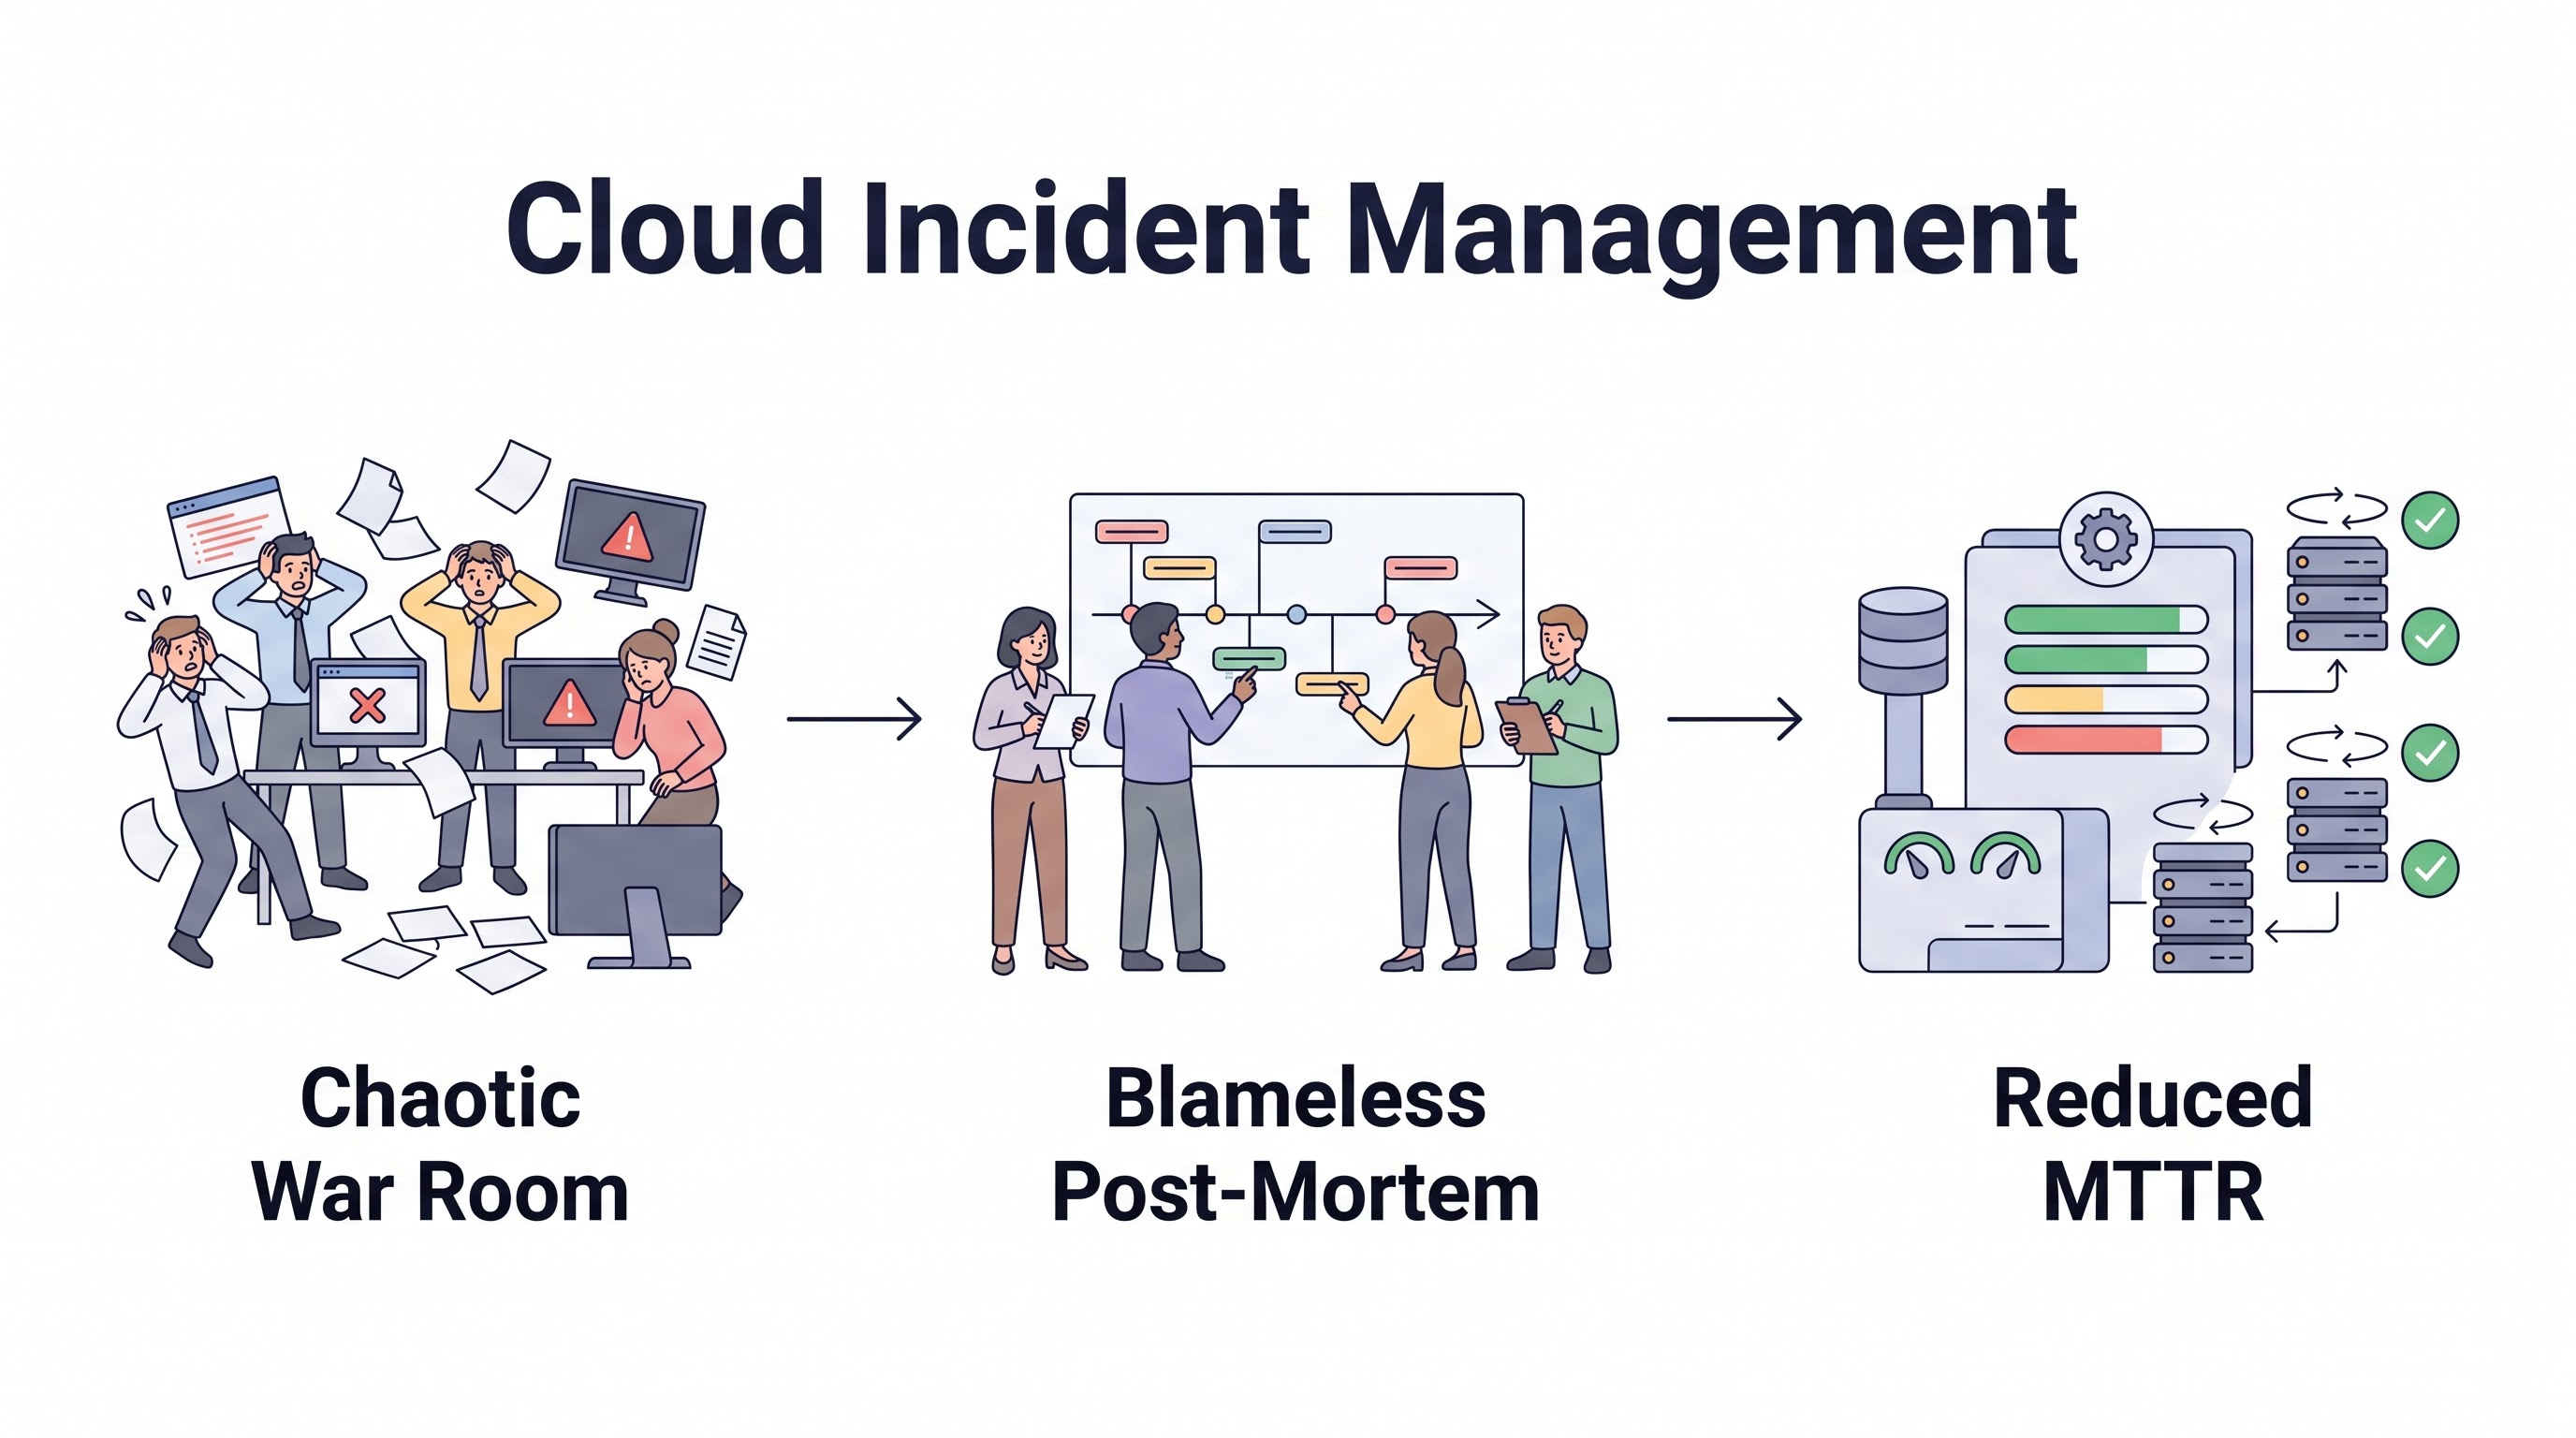
Mean Time to Resolution (MTTR): How long does it take to fix the problem once it is detected? MTTR encompasses triage, diagnosis, and mitigation. Reducing MTTR requires automated runbooks, clear communication channels, and blameless cultures.
The goal of incident management is to squash these two metrics as close to zero as possible.
The Incident Lifecycle
A chaotic response guarantees an extended MTTR. Successful organizations standardize the incident lifecycle.
1. Triage and Declaration
An alert fires (e.g., via PagerDuty). The on-call engineer assesses the alert. If the impact breaches a predefined threshold (e.g., "Checkout service error rate > 5%"), they officially declare a "Severity 1 Incident."
2. Swarming and Coordination
The declaration triggers automated workflows. A dedicated Slack channel is created (e.g., #inc-20260412-checkout-failure). A Zoom bridge is spun up. Crucially, the right experts are paged automatically based on the services involved.
3. Mitigation (Not Remediation)
During an active incident, the goal is mitigation (stopping the bleeding), not remediation (finding the perfect code fix). If a bad deployment caused the outage, you do not debug the code. You hit the "Rollback" button in the CI/CD pipeline to revert to the previous known-good state. Restore service to the customer first; debug later.
The Incident Command System (ICS)
Major incidents involving dozens of engineers degenerate into shouting matches without structure. Mature organizations adopt the Incident Command System (borrowed from emergency services).
Incident Commander (IC): The absolute authority during the incident. They do not write code or look at dashboards. They coordinate the response, make high-level decisions ("We are failing over to the secondary region"), and keep the team focused.
Communications Lead: Responsible for translating technical jargon into business impact. They update the public status page and brief executive stakeholders, keeping the C-suite off the IC's back.
Subject Matter Experts (SMEs): The engineers actively investigating logs and executing mitigations. They report their findings only to the IC.
The Blameless Post-Mortem
The incident is resolved. The MTTR is recorded. Now begins the most critical phase: The Post-Mortem.
If an organization's reaction to an outage is to find the engineer who deployed the bad code and fire them, that organization will never be secure or reliable. Why? Because the next time an engineer makes a mistake, they will hide it, delete the logs, and blame the network, increasing the MTTD of the next incident.
The Blameless Post-Mortem assumes that every engineer acted with the best intentions based on the information they had at the time. The focus is entirely on the systemic failures.
Wrong: "John took down the site by typing the wrong command."
Right: "The deployment pipeline lacked the guardrails to prevent a malformed command from executing against the production database."
Psychological safety is the prerequisite for reliability. Engineers must feel safe admitting mistakes so the organization can build systems to prevent those mistakes.
Root Cause Analysis is a Myth
In complex cloud systems, there is almost never a single "root cause." Outages are the result of multiple, compounding failures.
A post-mortem should explore the chain of events. A bad code commit (Event 1) passed CI/CD because a unit test was missing (Event 2). It deployed to production and caused a memory leak (Event 3). The auto-scaler failed to provision new nodes fast enough (Event 4), causing the database to be overwhelmed by retries (Event 5). The post-mortem must generate actionable engineering tickets (Action Items) to fix every link in that chain.
Automating the Incident Workflow
Incident management platforms (like PagerDuty or FireHydrant) automate the administrative toil of an incident. When a Sev 1 is declared, the platform automatically creates the Slack channel, updates the status page, assigns the Incident Commander role based on the on-call schedule, and begins assembling the timeline for the post-mortem based on Slack chat transcripts. This allows the engineers to focus 100% of their cognitive load on resolving the technical issue.
Key Takeaway
Robust cloud incident management requires accepting that failures will happen. Focus on reducing MTTD and MTTR through rigorous observability, standardized Incident Command structures, and aggressive automation. Most importantly, foster a blameless culture where post-mortems analyze systemic flaws rather than punishing human error. A solved incident that does not generate architectural improvements is a wasted opportunity.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.