The Dashboard Illusion
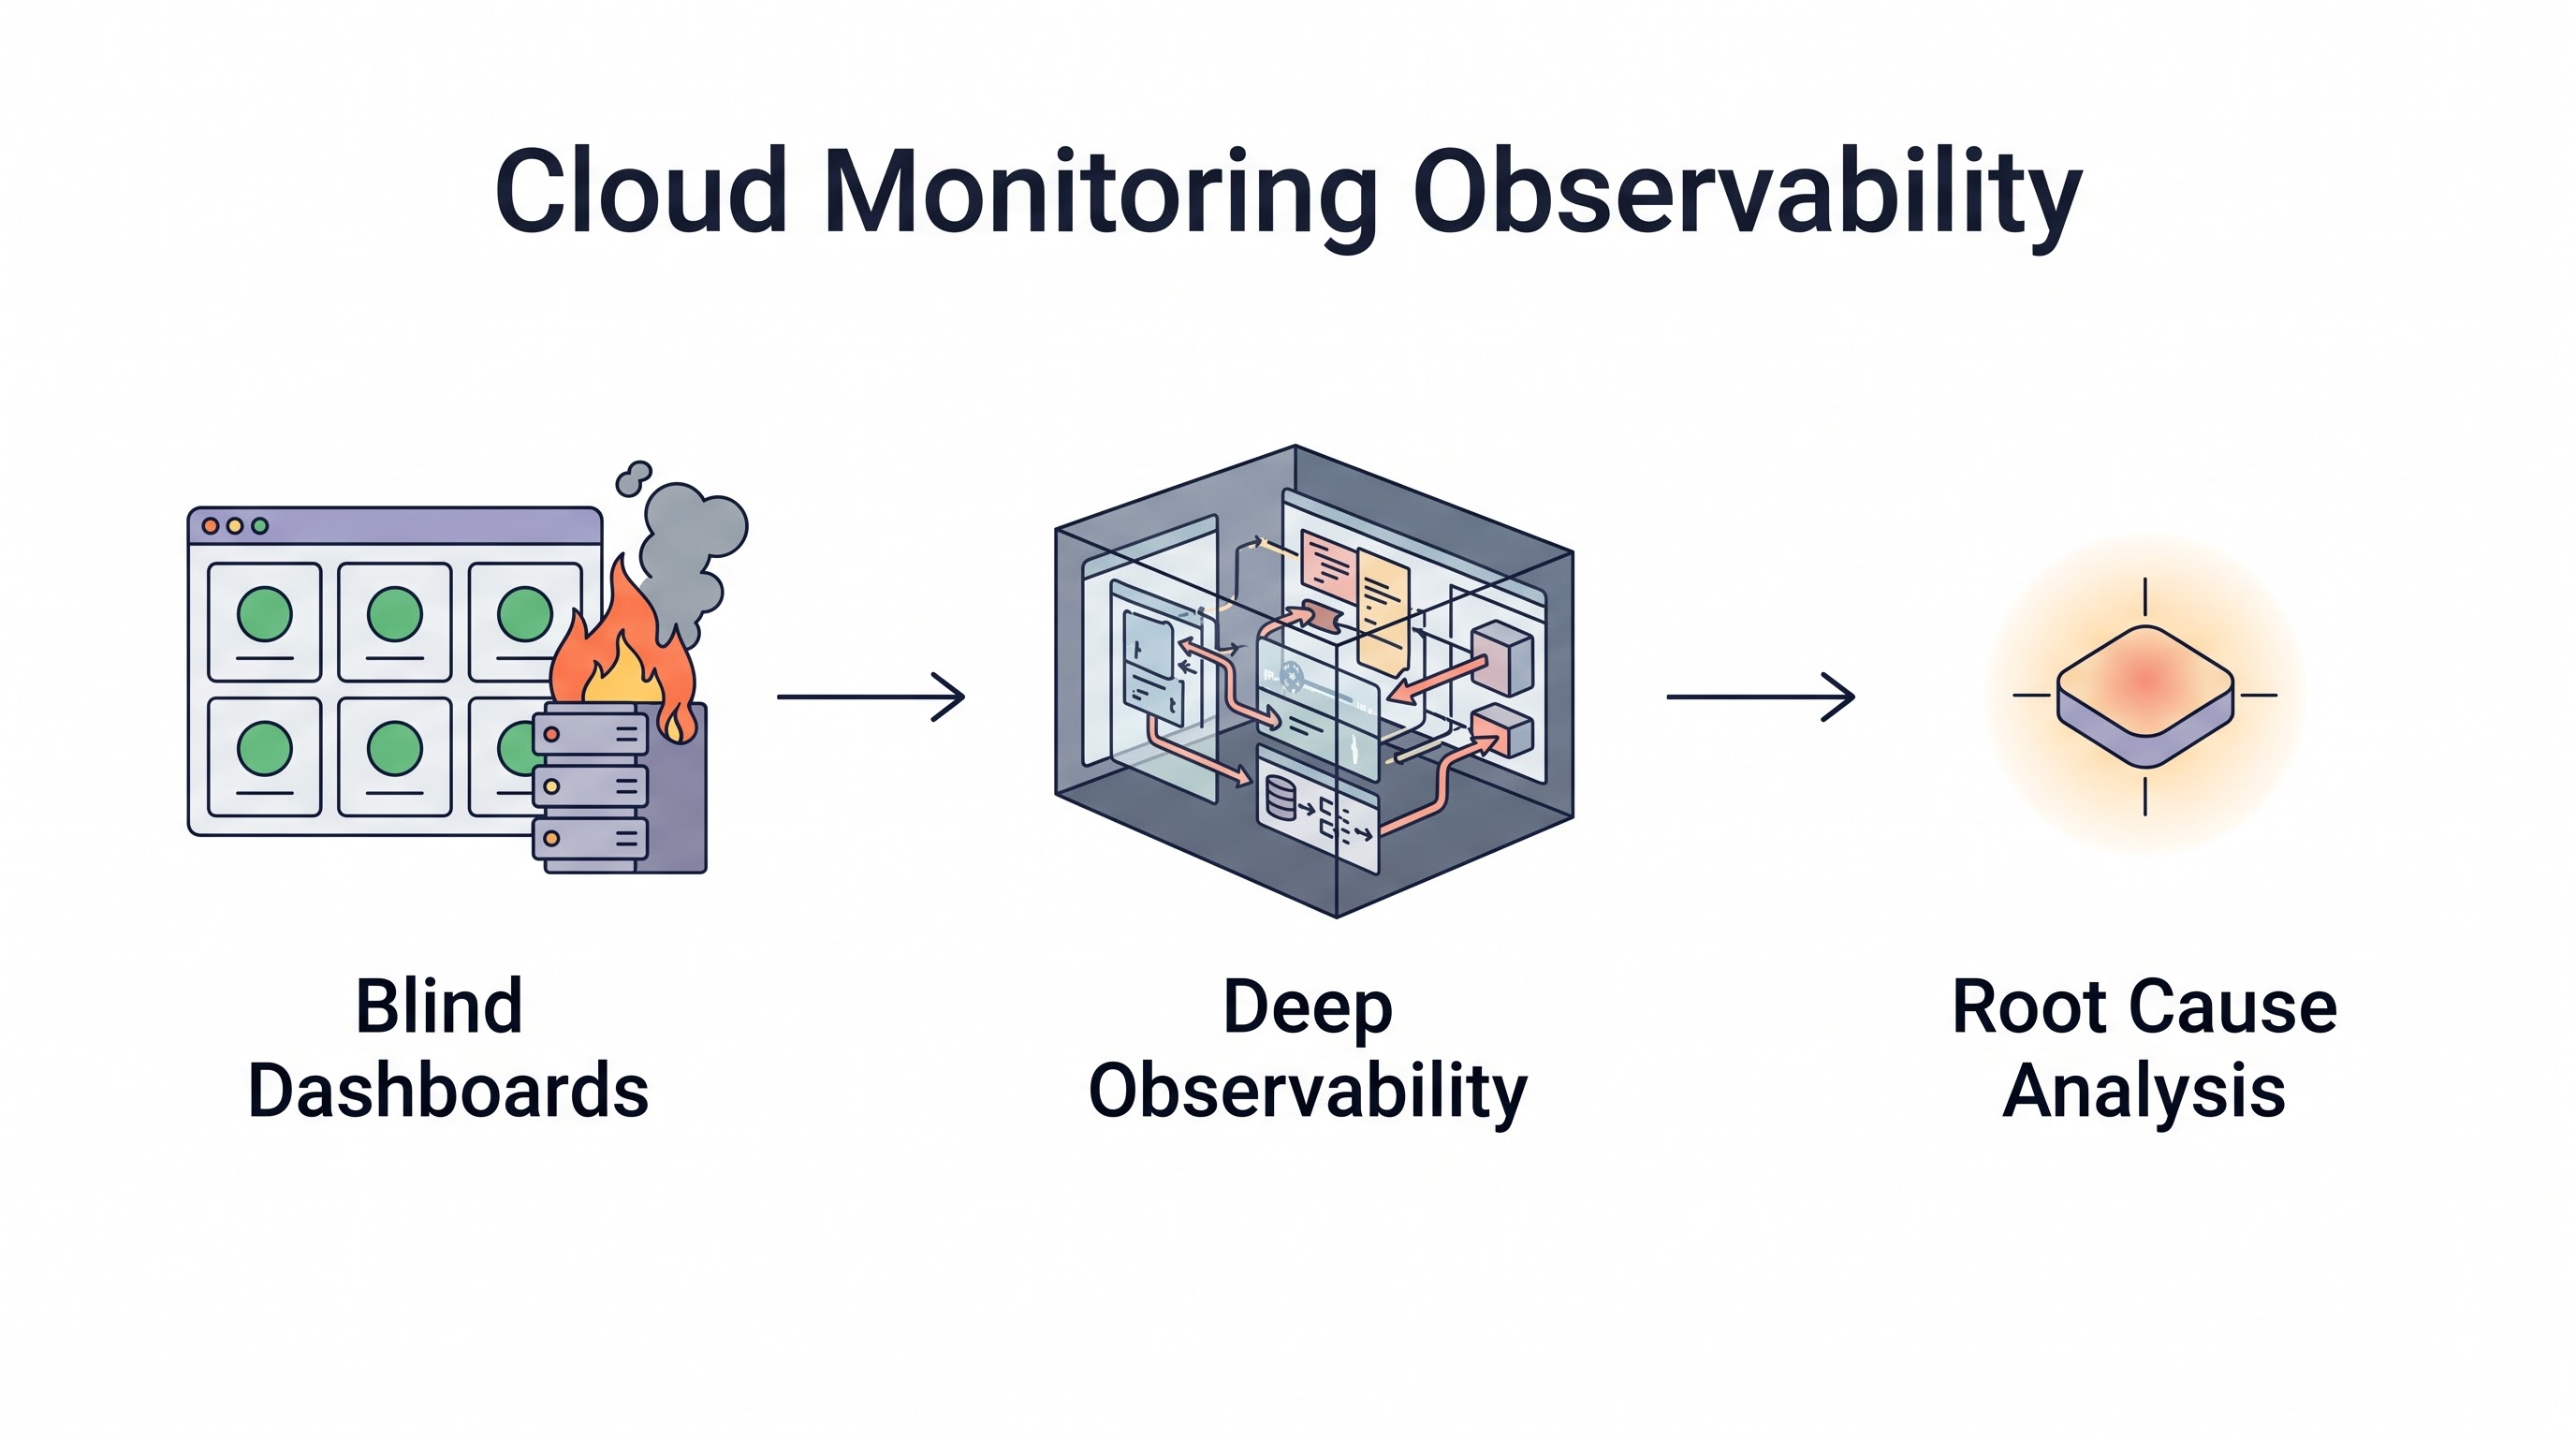
Walk into any Network Operations Center (NOC) and you will see walls covered in massive screens displaying hundreds of dashboards. Graphs spike, gauges turn red, and lines plummet. Yet, when a critical customer-facing application goes down, the engineers staring at those screens are often completely blind as to why.
In a traditional, monolithic architecture, monitoring CPU utilization and disk space on a single server was sufficient. If the CPU hit 100%, the application crashed. In a modern cloud-native architecture, an application might consist of 50 microservices running on ephemeral Kubernetes pods, communicating via serverless event buses across multiple availability zones. CPU utilization is no longer a reliable proxy for application health. A pod can have perfectly healthy resource metrics while completely failing to process transactions due to an invisible network timeout downstream.
To survive this complexity, Cloud Operations must evolve from Monitoring to Observability. This guide explains the technical distinction, the necessary tooling, and how to control the massive costs associated with capturing telemetry data.
Monitoring vs. Observability: The Core Difference
Monitoring tells you that a system is broken. It is a reactive measure based on predictable failure modes. You define what is bad (e.g., "Alert if HTTP 500 errors > 5%"), and the system watches for it.
Observability tells you why the system is broken. It is a proactive property of the system itself. An observable system emits enough high-quality data that an engineer can debug a novel, unpredictable failure mode—an "unknown unknown"—simply by asking questions of the data, without needing to inject new code to track down the bug.
Monitoring is staring at the dashboard. Observability is querying the underlying data lake to find the needle in the haystack.
The Three Pillars: Logs, Metrics, and Traces
True observability requires correlating data across three fundamental pillars.
Metrics (The "What"): Numerical representations of data measured over intervals of time (e.g., CPU %, memory usage, request rate). Metrics are cheap to store and incredibly fast to query. They are perfect for triggering alerts when SLIs deviate.
Logs (The "Details"): Immutable, timestamped records of discrete events (e.g., a user login failure, an application exception). Logs provide granular detail but are expensive to store and slow to search at petabyte scale.
Traces (The "Where"): The critical missing link in microservices. A trace represents the entire journey of a single user request as it traverses across dozens of different microservices and databases.
The Necessity of Distributed Tracing
If a user clicks "Checkout" and the request takes 8 seconds, looking at the logs of the frontend web server is useless; it will just show it waited 8 seconds. You need Distributed Tracing (APM).
Tracing injects a unique Trace ID into the HTTP header of the initial request. As that request flows from the web server to the cart service, to the payment gateway, to the database, the Trace ID is passed along. APM tools (Datadog, New Relic, Dynatrace) stitch these hops together into a waterfall chart. Instantly, the engineer sees that the 8-second delay was caused by the payment gateway making 40 redundant, sequential calls to a slow legacy database. Without tracing, finding that bottleneck in a microservice architecture is nearly impossible.
The OpenTelemetry Revolution
Historically, achieving observability meant vendor lock-in. If you chose Datadog, developers had to instrument the application code using the proprietary Datadog SDK. If the company wanted to switch to New Relic, developers had to rewrite the instrumentation code across 50 microservices.
OpenTelemetry (OTel), a CNCF project, solved this. OTel provides a single, vendor-agnostic standard for generating and collecting logs, metrics, and traces. Developers instrument the code once using OTel SDKs. The telemetry data is sent to an OTel Collector, which can route the data to any backend platform (Datadog, Prometheus, Splunk). OTel prevents vendor lock-in and is now the mandatory standard for modern cloud architectures.
The Observability Cost Explosion
Observability relies on data. As microservices scale, the volume of telemetry data explodes. It is highly common for the cost of an APM tool (which charges based on data ingested) to exceed the cost of the underlying AWS infrastructure it is monitoring.
This creates a severe FinOps crisis. Storing 100% of debug-level logs and 100% of traces for a high-volume application is financial suicide.
Strategies for Telemetry Cost Control
Tail-Based Sampling: Instead of capturing 100% of traces, you only need to capture the interesting ones. Tail-based sampling looks at the trace after it completes. If the trace represents a fast, successful HTTP 200 request, the data is dropped. If the trace contains an error or abnormal latency, 100% of the trace data is retained. This reduces ingestion costs by 90% without losing critical debug data.
Metric-to-Log Conversion: Don't use logs to count things. If you are logging a line every time a user logs in, simply to count daily active users, you are wasting money. Increment a metric counter instead, and disable the log line.
The Observability Pipeline: Utilize tools like Vector or Cribl to sit between your applications and your expensive APM vendor. These pipelines allow you to parse, filter, deduplicate, and route data before you pay for ingestion. You can route expensive, verbose logs to cheap S3 storage for compliance, while routing only critical error logs to Datadog for alerting.
Key Takeaway
Dashboards only tell you what is happening; observability allows you to ask why. Moving from traditional monitoring to full-stack observability requires implementing distributed tracing to understand request flows in complex microservice environments. Standardize on OpenTelemetry to avoid vendor lock-in, and aggressively implement sampling and observability pipelines to prevent your telemetry costs from eclipsing your infrastructure costs.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.