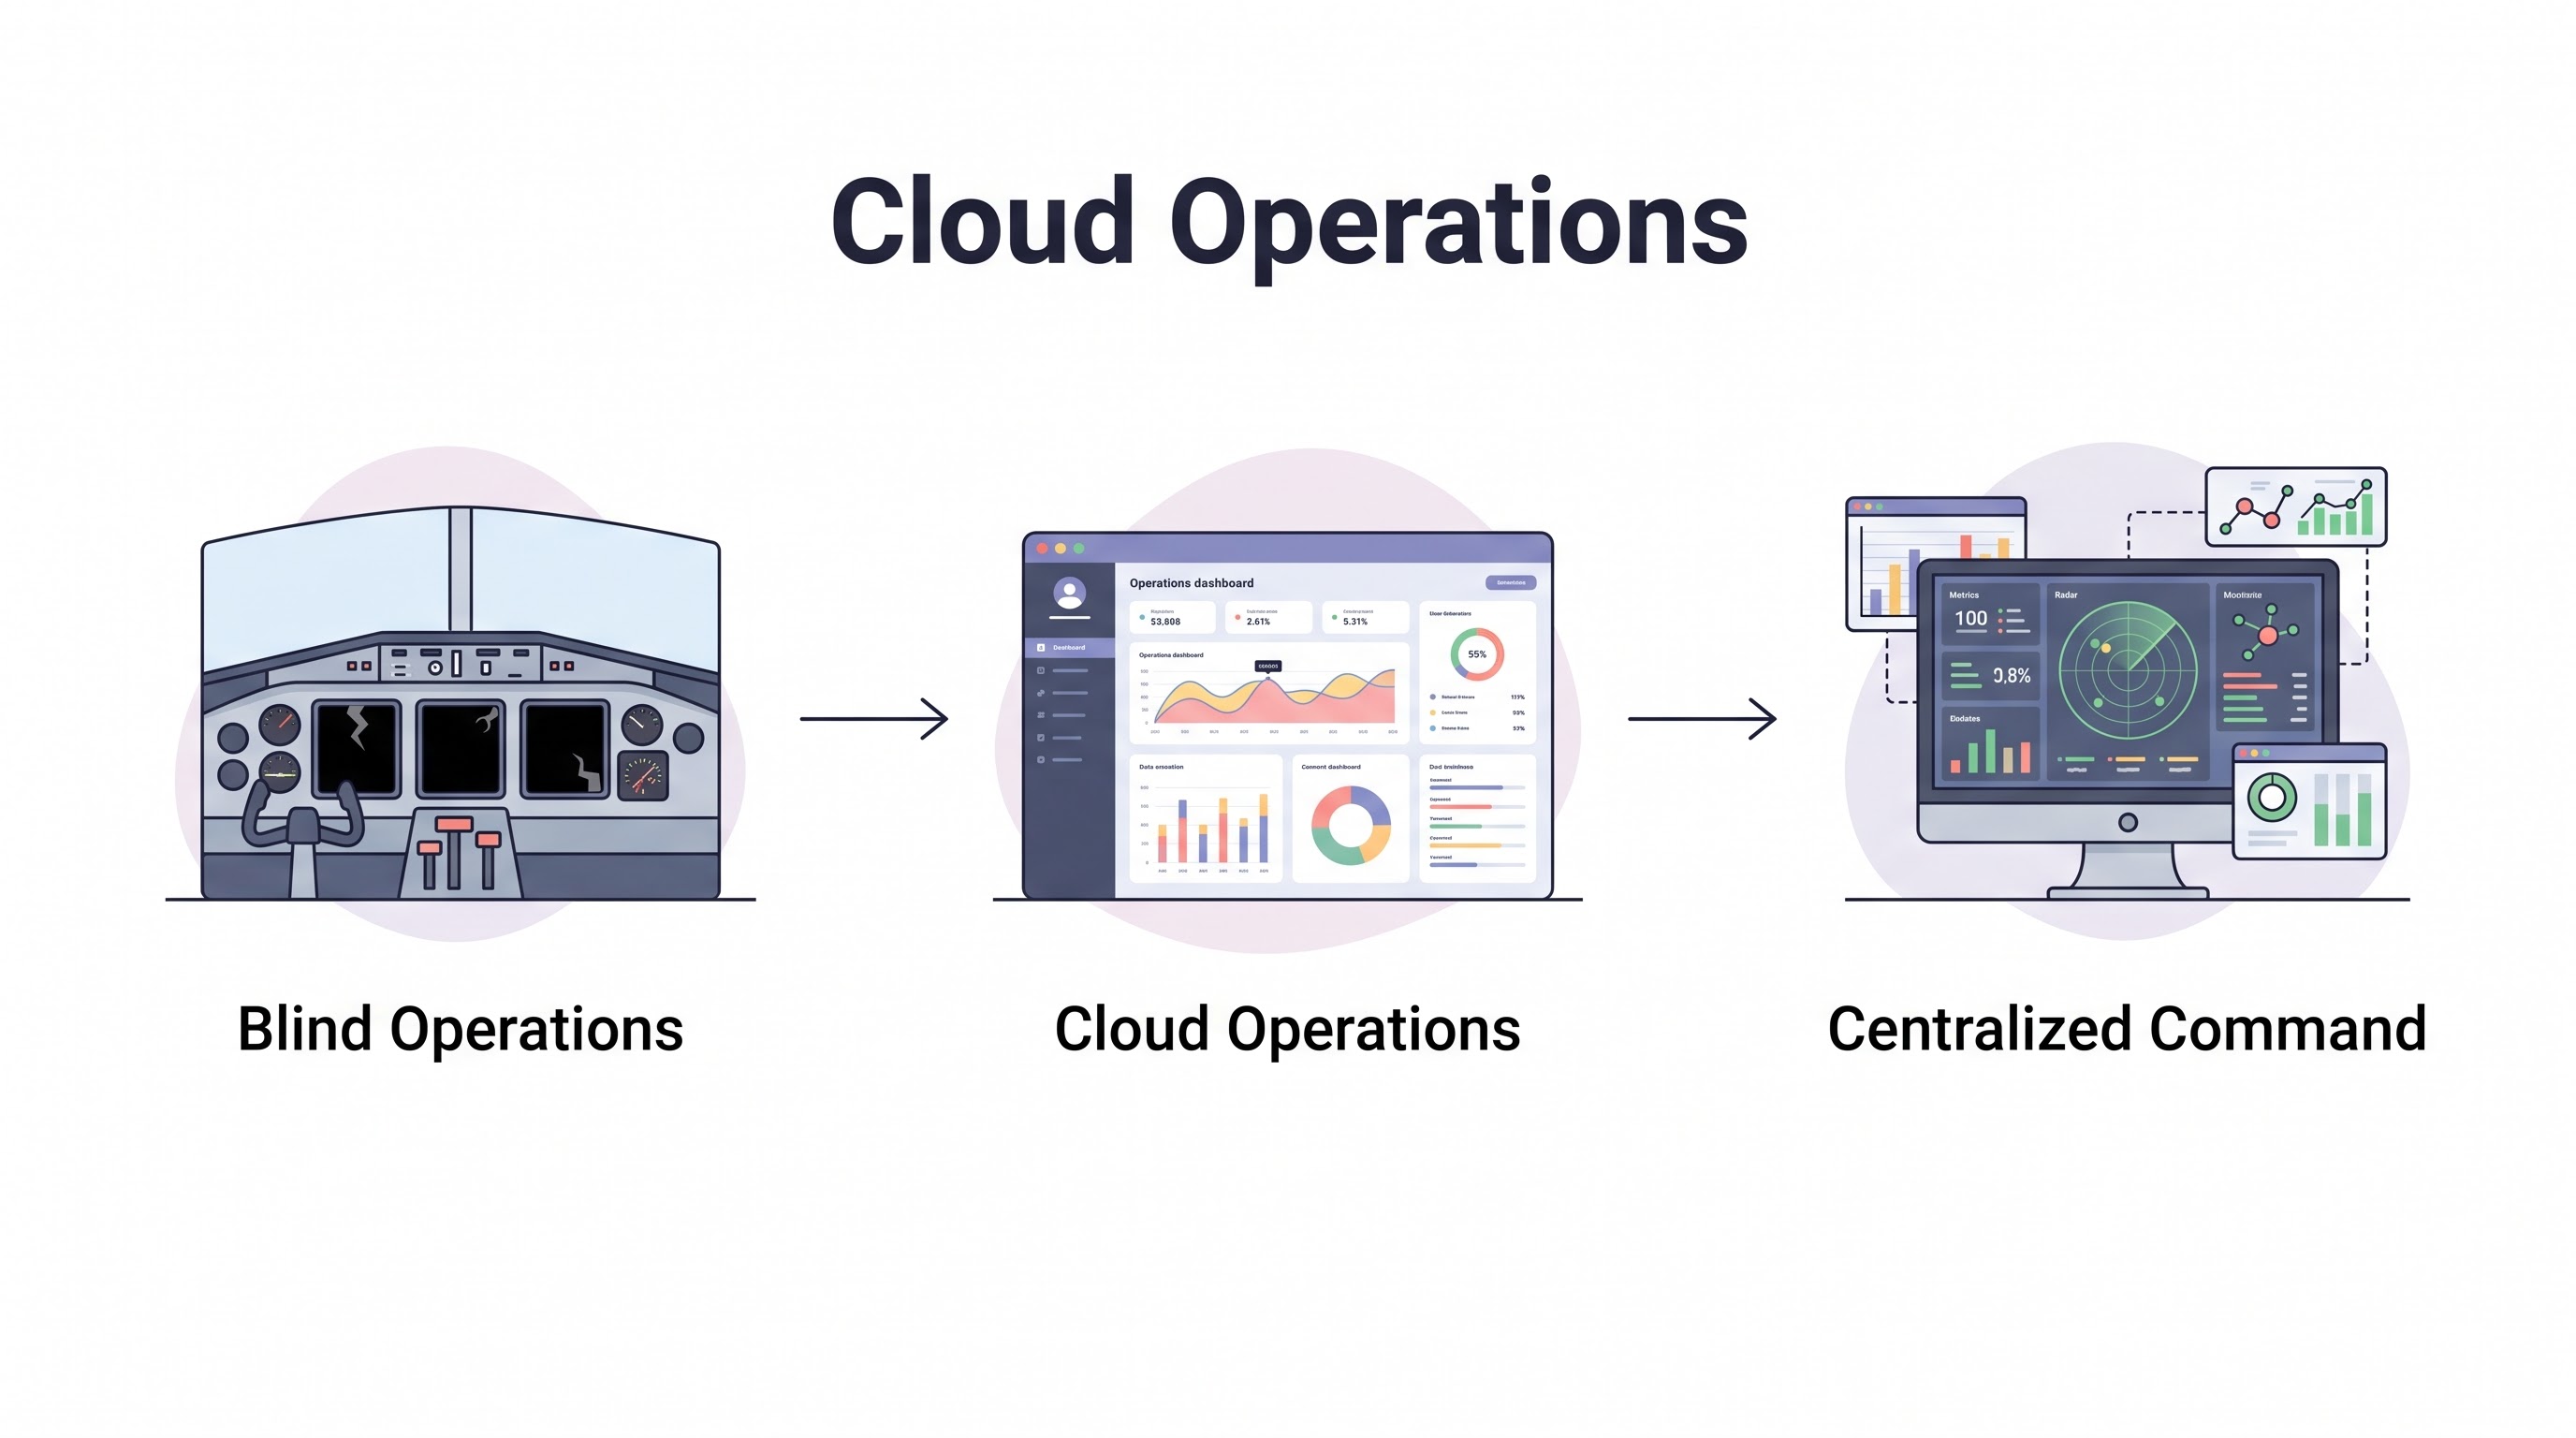
The Evolution of Ops
The role of "Operations" in IT has undergone a radical transformation over the last decade. We moved from the traditional SysAdmin (racking servers and manually patching Linux kernels) to the DevOps Engineer (automating deployments via CI/CD). However, as cloud architectures evolved from simple EC2 instances to complex, multi-cloud Kubernetes clusters and serverless meshes, the "DevOps" model began to fracture under its own weight.
In 2026, Cloud Operations is no longer a single discipline. It is a highly specialized ecosystem encompassing Site Reliability Engineering (SRE) for stability, and Platform Engineering for developer velocity. This guide explores how mature organizations are structuring their Cloud Ops teams to handle the staggering complexity of modern infrastructure.
Why DevOps Reached Its Limits
The original promise of DevOps was "You build it, you run it." Developers were expected to write the application code, write the Terraform to provision the infrastructure, configure the CI/CD pipeline, and hold the pager if the database crashed at 3:00 AM.
This model works flawlessly for a 10-person startup. At enterprise scale, it is a disaster. The cognitive load required for a developer to master React, Node.js, Kubernetes network policies, AWS IAM roles, and Prometheus PromQL is impossibly high. Developers ended up spending 50% of their time writing YAML files instead of shipping business features. The "shift left" movement accidentally shifted the entire operational burden onto the developer.
Site Reliability Engineering (SRE): The Math of Reliability
Pioneered by Google, Site Reliability Engineering treats operations as a software engineering problem. SREs are software engineers tasked with building systems that guarantee high availability.
SRE is governed by strict mathematics:
Service Level Indicators (SLIs): What are we measuring? (e.g., the latency of the checkout API API, or the error rate of HTTP requests).
Service Level Objectives (SLOs): What is our target? (e.g., 99.9% of checkout API requests will complete in under 200ms).
Error Budgets: The inverse of the SLO (e.g., a 0.1% allowance for errors). If the engineering team burns through their error budget for the month due to unstable deployments, all new feature launches are halted until stability is restored.
SREs do not exist to manually restart crashed servers. They exist to eliminate toil through automation. If an SRE is performing a task manually a third time, their job is to write a script that prevents the task from ever occurring again.
The Rise of Platform Engineering
If SRE handles reliability, Platform Engineering handles velocity. Platform Engineering emerged to solve the cognitive overload problem of DevOps.
Instead of expecting every developer to become an AWS expert, the Platform Engineering team builds a centralized, secure, and highly automated platform that abstracts away the complexity of the underlying cloud. They treat the development teams as their internal customers.
The Internal Developer Platform (IDP)
The physical manifestation of Platform Engineering is the Internal Developer Platform (IDP) (e.g., using frameworks like Backstage). An IDP is a self-service portal for developers.
When a developer wants to create a new microservice, they do not write a Terraform module from scratch. They log into the IDP, click "Create New Microservice," and fill out a web form. The IDP automatically:
Provisions a new GitHub repository with the correct boilerplate code.
Creates the secure CI/CD pipeline.
Provisions the underlying Kubernetes namespace or ECS cluster.
Configures the necessary IAM roles with least privilege.
Sets up the default Datadog dashboards and PagerDuty alerts.
The developer is ready to write business logic in 5 minutes, completely insulated from the underlying infrastructure complexity.
Paving the Golden Paths
Platform teams build "Golden Paths" (or paved roads). A Golden Path is an officially supported, highly automated way of doing things. For example, "Deploying a Spring Boot container to EKS using PostgreSQL."
Developers are not forced to use the Golden Path, but if they choose to use a non-standard technology (e.g., deploying a Haskell application to an obscure NoSQL database), they must support the infrastructure themselves. Given the choice, 95% of developers will choose the Golden Path because it is frictionless.
Integrating FinOps and SecOps
The genius of the Platform Engineering model is that it becomes the ultimate enforcement mechanism for security and cost efficiency.
SecOps Integration: The Platform team bakes security into the IDP templates. The auto-generated CI/CD pipeline already contains the necessary SCA and SAST scanners. The pre-configured IAM roles are already compliant with Zero Trust policies.
FinOps Integration: The Platform team configures the templates to use cost-effective resources by default (e.g., defaulting to ARM-based Graviton processors, or automatically applying cost allocation tags to every resource provisioned through the IDP).
Ops as a Product
In 2026, Cloud Operations is no longer a ticket-taking IT department. It is a product organization. The SREs ensure the product is available, and the Platform Engineers ensure the product is user-friendly. By abstracting the crushing complexity of the multi-cloud ecosystem into automated, secure Golden Paths, organizations can finally realize the velocity promises of the cloud era without sacrificing stability or security.
Key Takeaway
The era of "You build it, you run it" has evolved. To prevent developer burnout and ensure enterprise-grade security and reliability, modern Cloud Operations must adopt Platform Engineering. Build an Internal Developer Platform (IDP) that abstracts cloud complexity into self-service Golden Paths, embedding SRE reliability principles, SecOps compliance, and FinOps efficiency directly into the templates developers use every day.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.