The Compounding Cost of Data
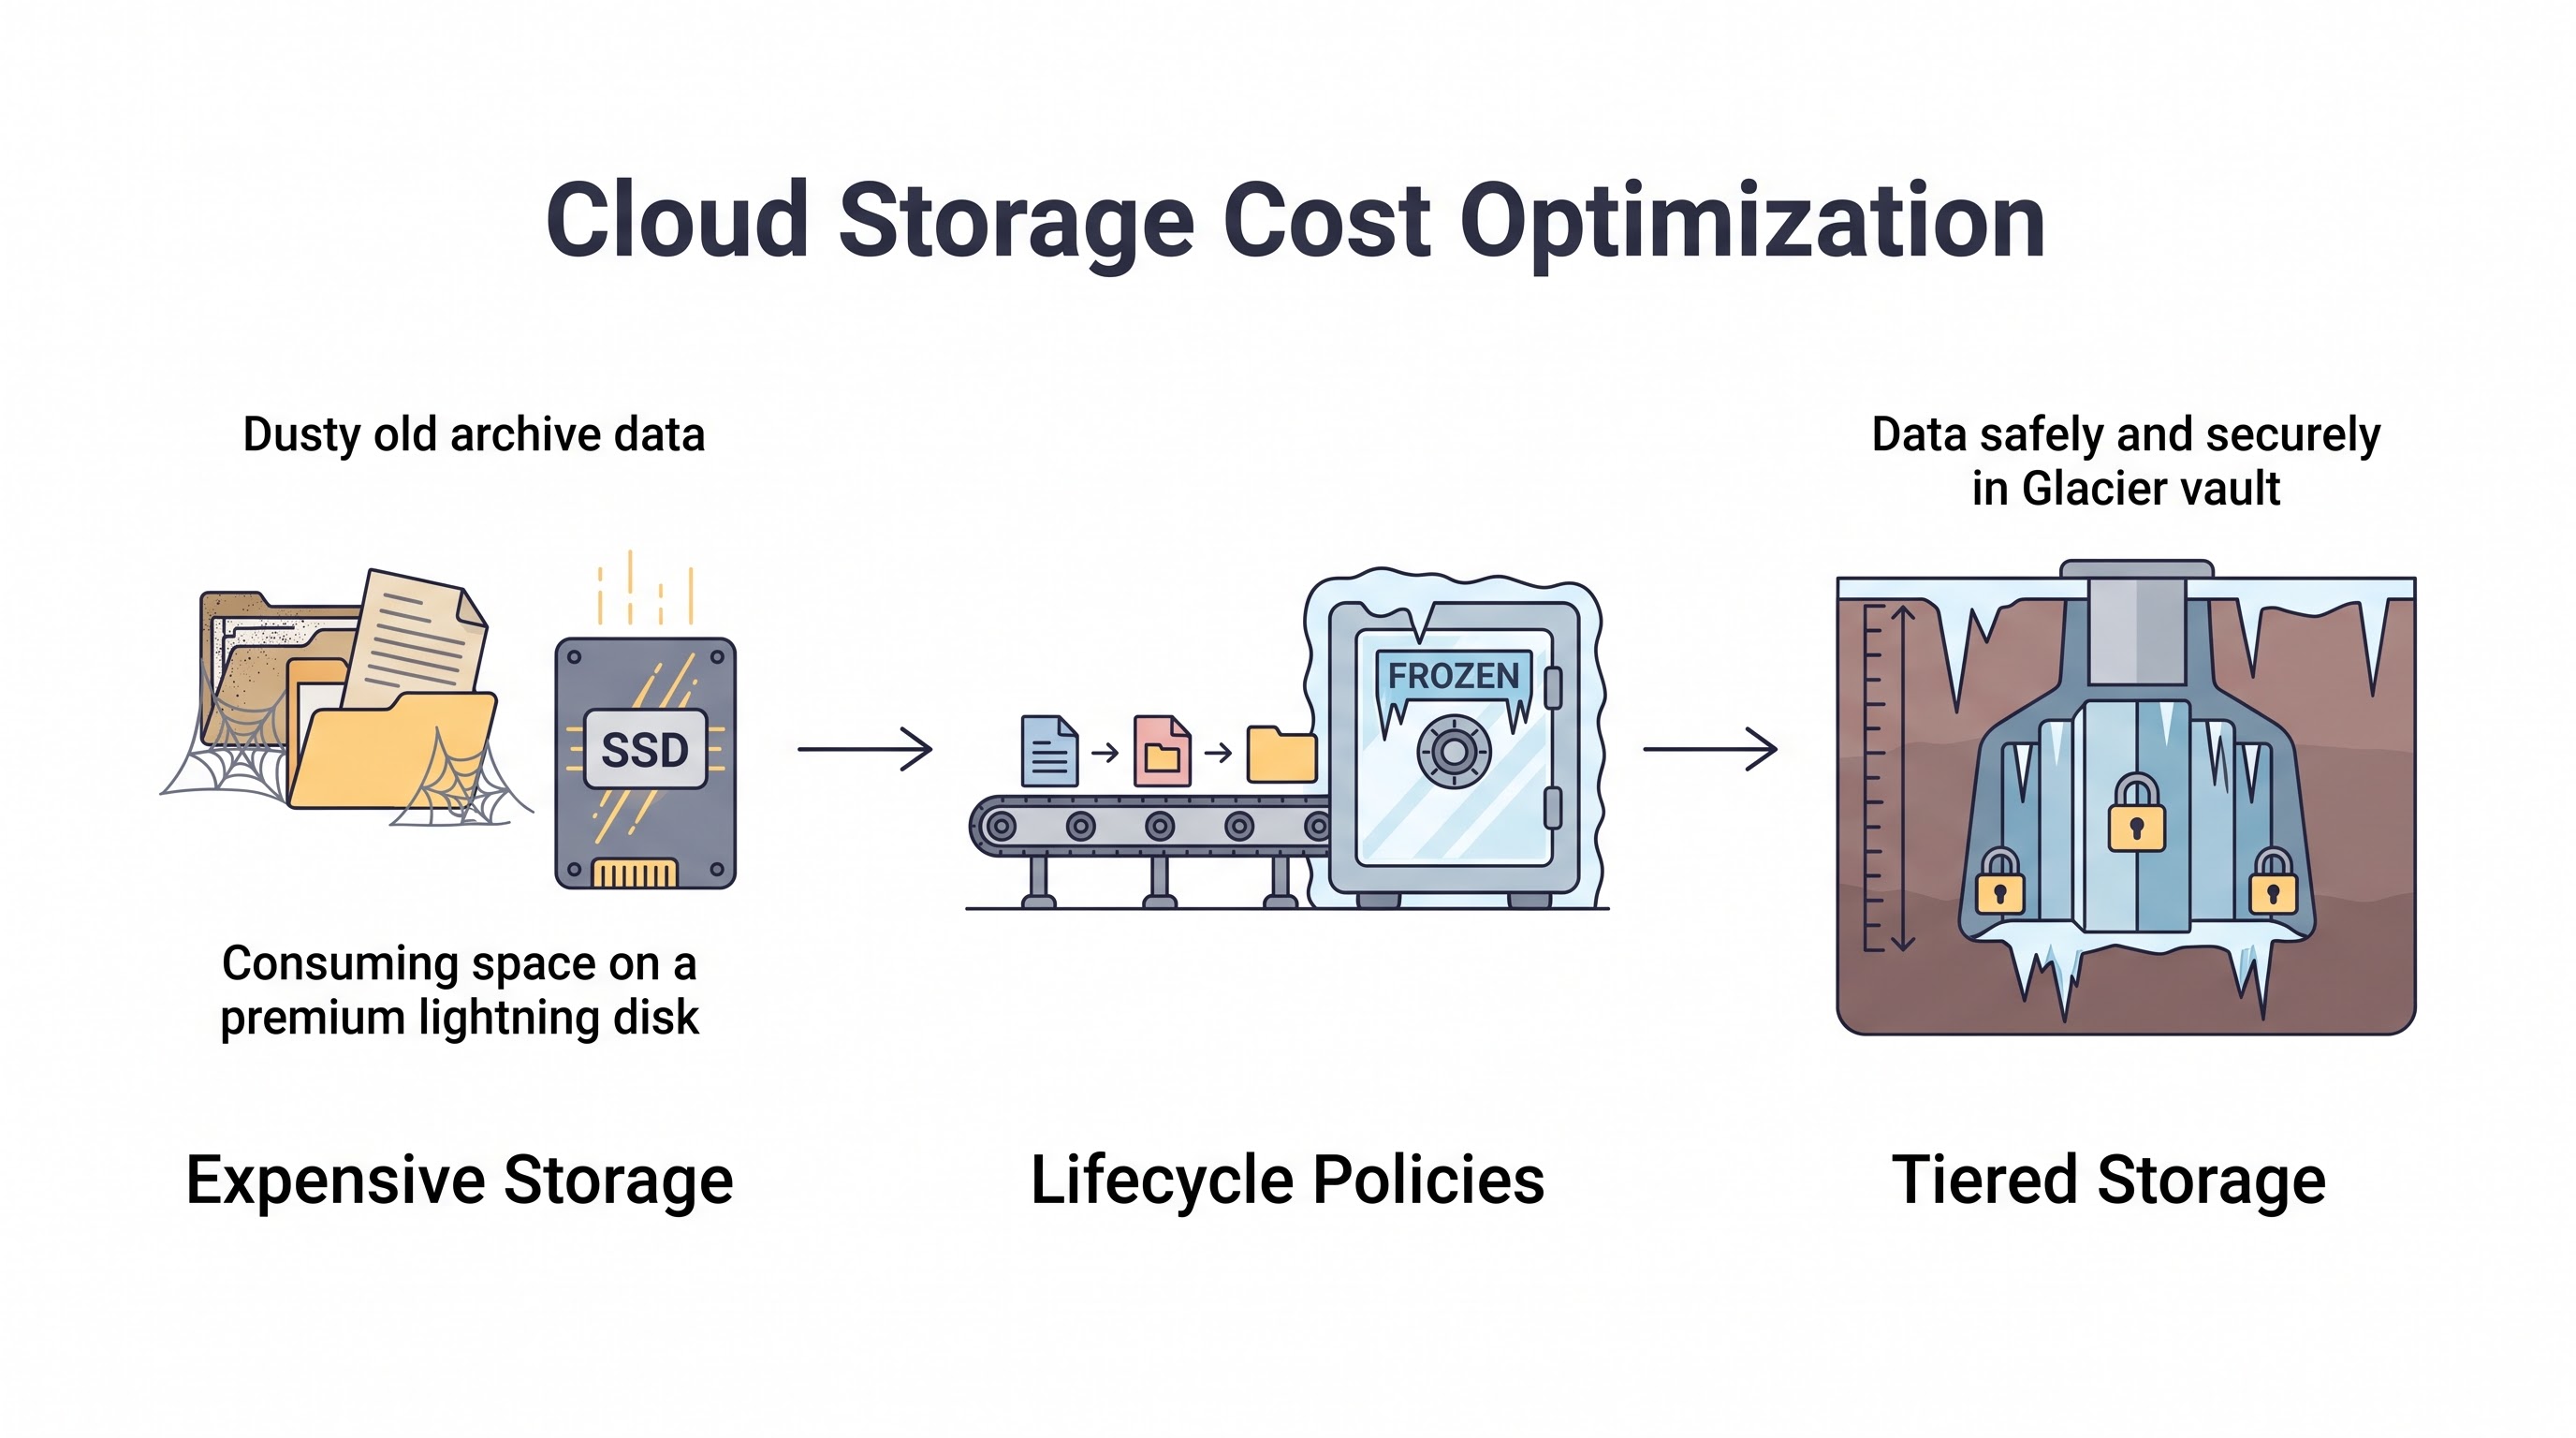
Data has gravity, and it never stops growing. Unlike compute instances that can be terminated at night or scaled down during low traffic, storage costs are persistent and compounding. Organizations routinely hoard petabytes of ancient log files, forgotten database backups, and unattached hard drives, paying premium rates for data they haven't accessed in years.
Optimizing cloud storage is the lowest-hanging fruit in FinOps. Unlike refactoring an application to use less compute, storage optimization rarely requires developer intervention and carries almost zero risk to application uptime. This guide details the tactics required to clean up block storage and automate the lifecycle of object storage.
Block Storage (EBS): The Zombie Volumes
Block storage (AWS EBS, Azure Managed Disks) acts as the physical hard drive for virtual machines. It is expensive.
The most common source of storage waste is the Unattached Volume. When an engineer terminates an EC2 instance, the default behavior in AWS (for secondary data volumes) is to leave the EBS volume alive. It sits in the account, completely disconnected from any server, generating a bill every single hour. Organizations routinely discover tens of thousands of dollars of "zombie" EBS volumes.
The Fix: Implement automated lambda functions (or use CSPM tools) to scan the account daily. If an EBS volume has been in the "Available" (unattached) state for more than 14 days, the automation should take a final, cheap snapshot of the volume, and then delete the expensive EBS volume entirely.
Rightsizing and Modernizing EBS
Even attached volumes are heavily mismanaged.
Overprovisioning: Developers routinely provision 500GB drives for operating systems that only require 20GB. Utilize observability tools to track disk usage. If a volume is 10% full, create a smaller volume, migrate the data, and terminate the oversized drive.
Generational Upgrades: As discussed in the Database Optimization Guide, legacy
gp2volumes in AWS bundle capacity and IOPS together. By executing a zero-downtime migration to the moderngp3standard, organizations instantly reduce their storage bill by up to 20% while gaining the ability to tune IOPS independently.
Object Storage (S3): Understanding the Tiers
Amazon S3 is the dumping ground of the internet. Optimizing it requires understanding that not all data is equal. AWS offers distinct storage tiers based on access patterns:
S3 Standard: The default. High storage cost, but zero cost to retrieve the data. Best for active, hot data.
S3 Standard-IA (Infrequent Access): Lower storage cost, but you are charged a fee every time you retrieve the data. Best for data accessed less than once a month.
S3 Glacier Instant Retrieval: Very low storage cost, high retrieval fees. Data is available immediately.
S3 Glacier Deep Archive: The absolute cheapest storage (fractions of a penny per GB). However, retrieving data takes 12-48 hours and carries massive fees. Best for compliance data that will likely never be read again.
Automating Savings: Lifecycle Policies
You cannot manually move petabytes of data between tiers. You must implement S3 Lifecycle Policies.
A Lifecycle Policy is a rule applied to a bucket (or specific prefixes/tags). For example, a policy for an application's log files might dictate:
Days 1-30: Keep in S3 Standard (for active debugging).
Days 31-90: Move to S3 Standard-IA (for occasional audits).
Days 91-365: Move to S3 Glacier Deep Archive (for compliance retention).
Day 366: Permanently Delete.
This automation ensures data naturally flows toward the cheapest possible tier as it cools, without any human intervention.
The Easy Button: S3 Intelligent-Tiering
For workloads where access patterns are completely unpredictable (e.g., a data lake where data scientists query random datasets sporadically), configuring strict lifecycle policies is difficult.
For these scenarios, enable S3 Intelligent-Tiering. You pay a tiny monitoring fee per object. AWS automatically monitors the access patterns. If an object isn't accessed for 30 days, AWS moves it to the Infrequent Access tier. If it's not accessed for 90 days, it moves to Archive. If it is suddenly accessed again, it is instantly moved back to the Frequent Access tier, with no retrieval fees.
For large, unpredictable buckets, enabling Intelligent-Tiering is the "easy button" that guarantees long-term savings.
The Hidden Trap: Data Retrieval Costs
The primary trap of storage optimization is misunderstanding retrieval fees. If you move a bucket containing active web assets (CSS files, Javascript) to S3 Standard-IA to save on storage costs, you will trigger retrieval fees thousands of times a second as users load the website. The retrieval fees will be exponentially higher than the storage savings.
Never move data to an Infrequent Access or Glacier tier unless you are mathematically certain that the data is truly "cold."
Key Takeaway
Cloud storage optimization is an exercise in hygiene and automation. Aggressively identify and terminate unattached "zombie" EBS volumes, and migrate legacy gp2 volumes to the modern, cheaper gp3 standard. For S3 object storage, implement Lifecycle Policies to automatically transition aging data to cheaper Glacier tiers, and default to S3 Intelligent-Tiering for data lakes with unpredictable access patterns to optimize costs automatically.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.