The Kubernetes Billing Black Box
Kubernetes is highly efficient at orchestrating containers, but it is notoriously terrible at explaining how much those containers cost. When an organization migrates from traditional EC2 instances to Amazon EKS, the finance team often loses all visibility into unit economics. The monthly AWS bill simply shows a massive, monolithic charge for "EC2 instances in the EKS cluster."
If the EKS cluster hosts 40 different microservices belonging to 6 different engineering teams, how do you determine which team is responsible for the cost? How do you know if the "Checkout" service is wildly inefficient or if the "Recommendation Engine" is burning cash?
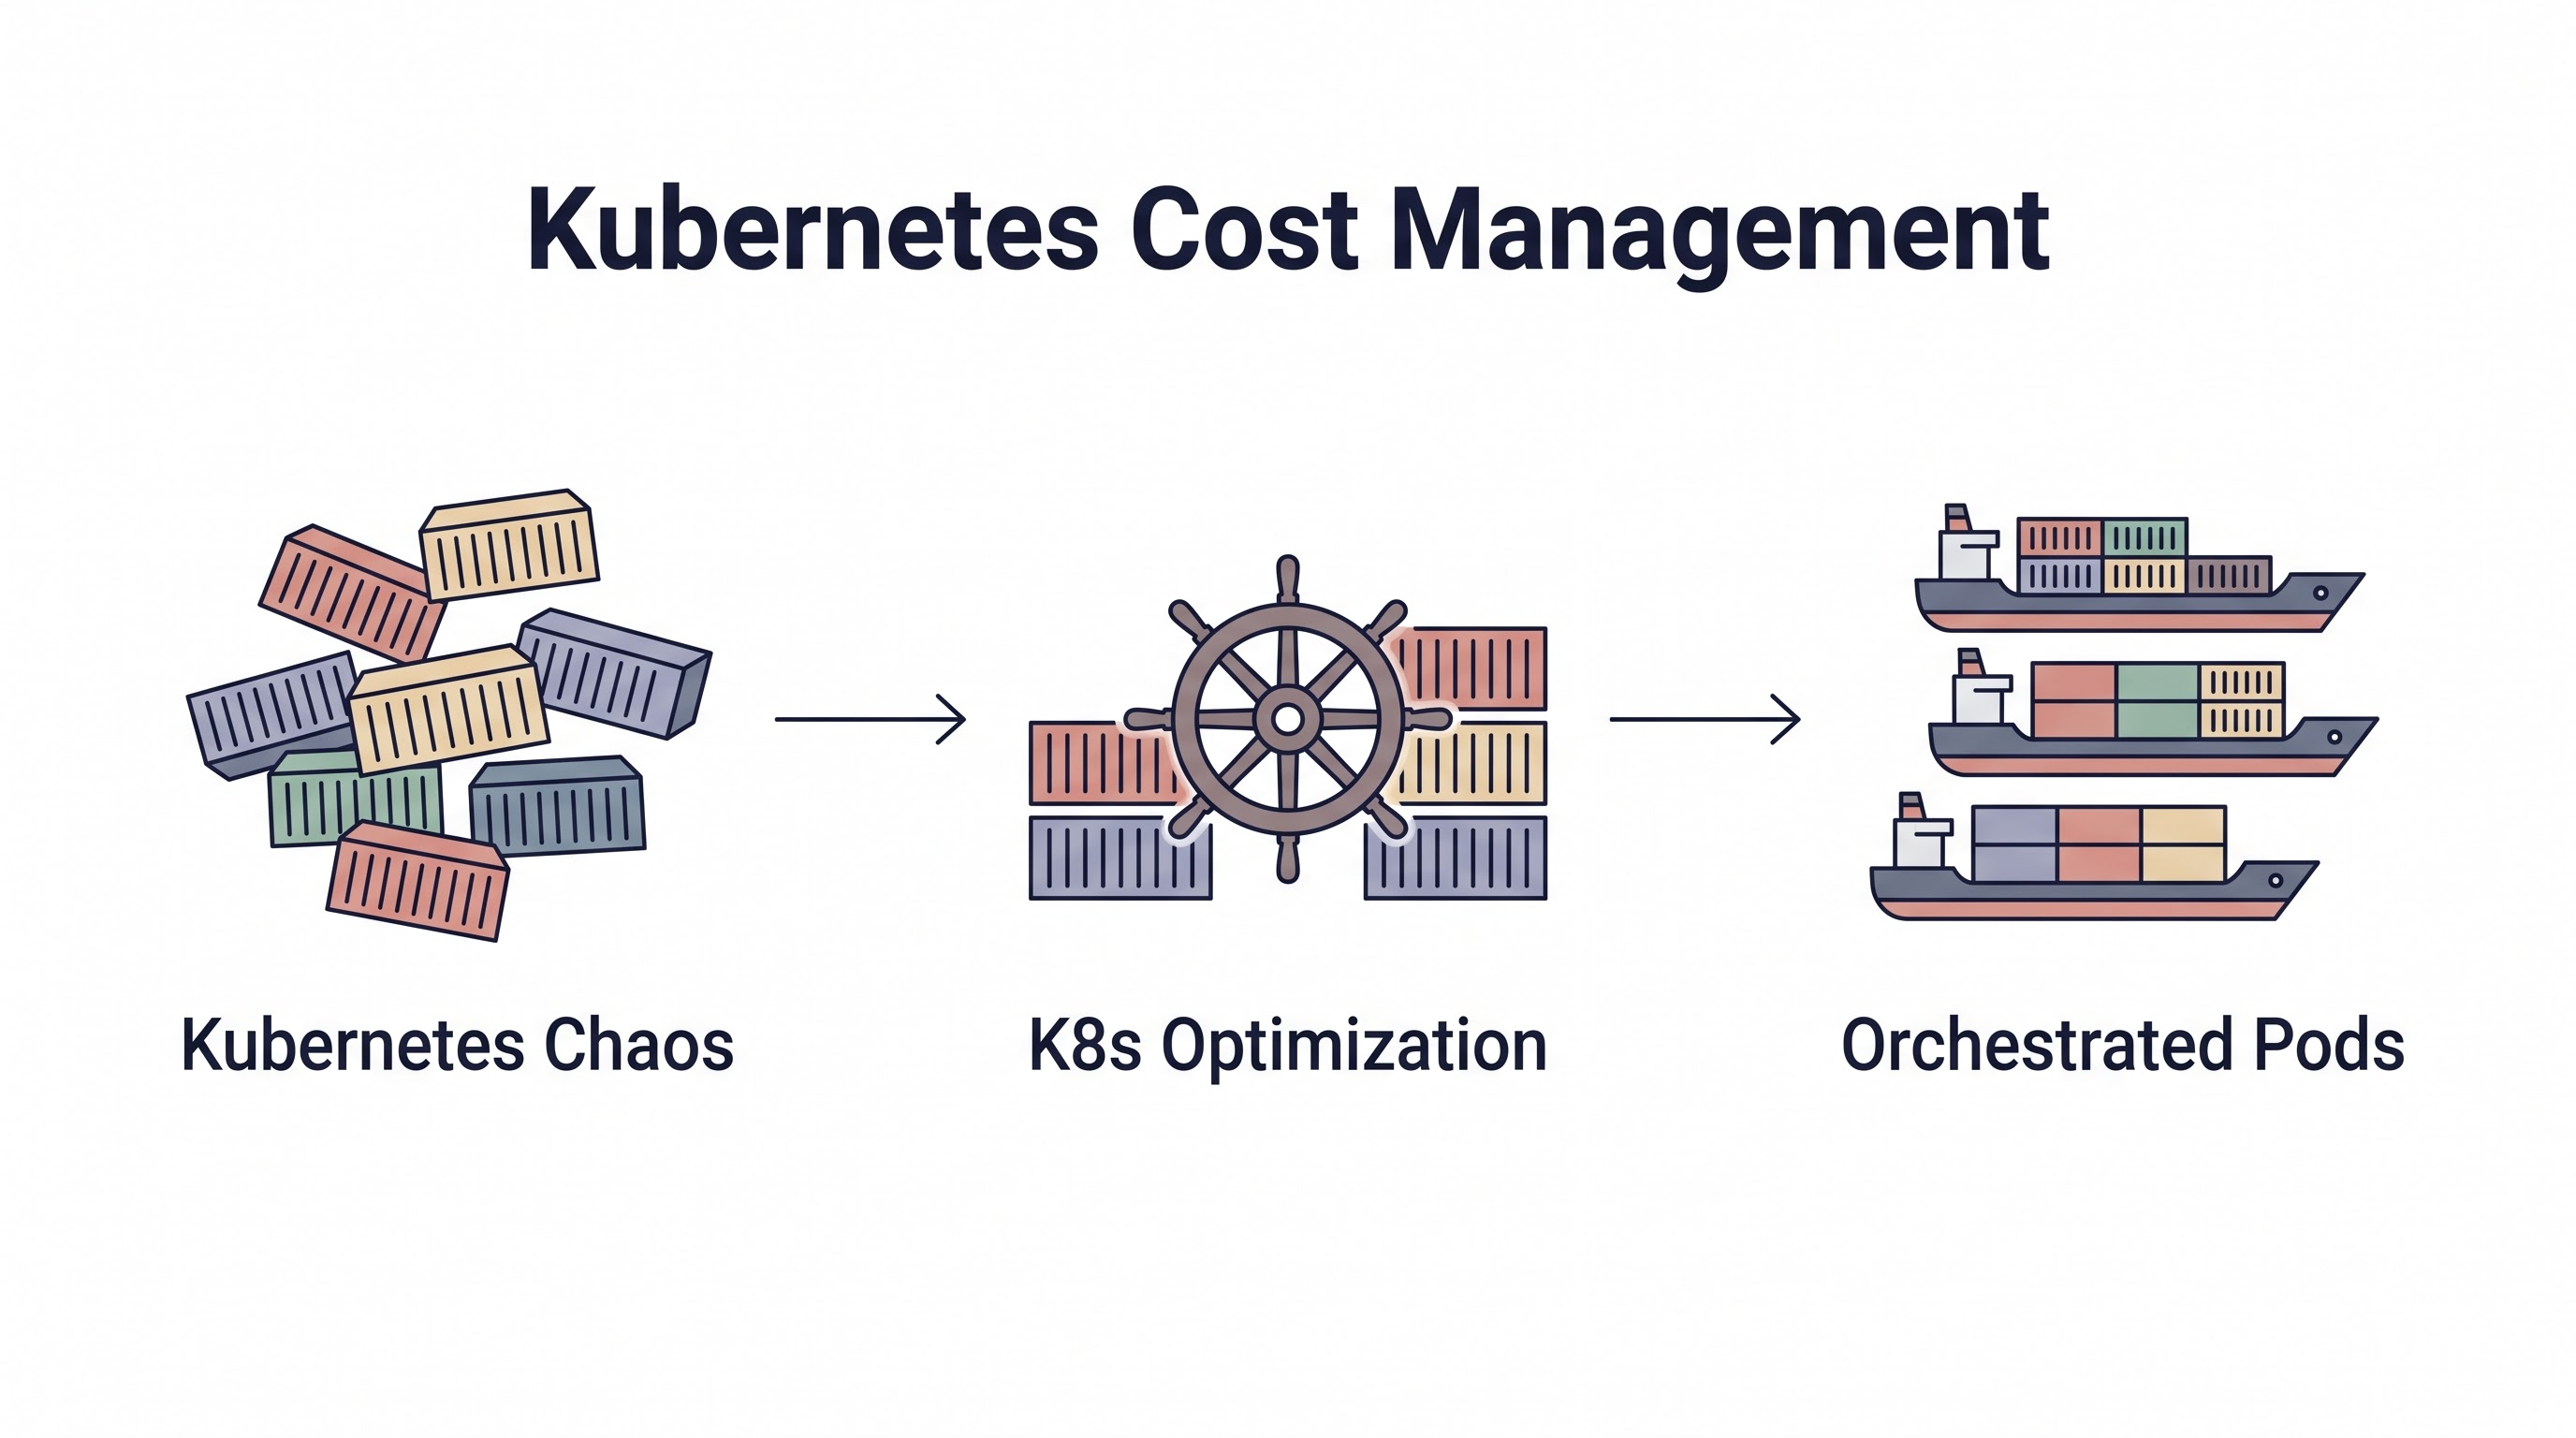
This is the black box of Kubernetes cost management. Unlocking it requires specialized tooling and strict discipline regarding resource requests. This guide explains how to attribute Kubernetes costs accurately and the specific levers required to optimize them.
The Visibility Problem: Cloud Bills Don't Speak K8s
The fundamental disconnect is that cloud providers bill based on physical (or virtualized) infrastructure: EC2 instances, EBS volumes, and NAT Gateways. Kubernetes operates on logical constructs: Namespaces, Deployments, and Pods.
Standard cloud tags do not easily penetrate the cluster. If you tag the underlying EC2 worker node as Team: Shared, that doesn't tell you which pod is consuming the CPU on that node. Without that translation layer, chargeback and showback models completely collapse.
Decoding the Box: Kubecost and OpenCost
To solve the visibility problem, you must deploy a Kubernetes-native cost monitoring tool like Kubecost (built on the CNCF OpenCost standard).
Kubecost runs inside the cluster as a DaemonSet. It continuously queries the Kubernetes API to determine exactly how much CPU, memory, and storage every single pod is consuming. It then connects to the cloud provider's billing API (e.g., AWS Cost and Usage Report) to determine the exact hourly rate of the underlying nodes.
By blending these two datasets, Kubecost can finally answer the critical question: "How much did the frontend deployment in the production namespace cost yesterday?" It translates abstract pod metrics into actual dollar amounts, allowing organizations to resume accurate chargeback reporting.
The Core Culprit: Requests vs. Limits
Once you have visibility, you inevitably discover massive waste. The primary cause of wasted spend in Kubernetes is misconfigured Pod resource requests.
When a developer defines a Pod, they set two values for CPU and Memory:
Requests: The amount of resources the cluster guarantees to the Pod. If you request 2 vCPUs, the Kubernetes scheduler reserves 2 vCPUs on a node exclusively for that Pod.
Limits: The maximum amount of resources the Pod is allowed to burst up to before being throttled (CPU) or killed (Memory/OOM).
The Mistake: Developers, fearing out-of-memory crashes, set massive Requests (e.g., Requesting 4GB of RAM for a pod that only uses 500MB). The scheduler reserves the 4GB. That space cannot be used by any other pod. The node appears "full" to the scheduler, forcing the cluster to spin up new, expensive EC2 worker nodes, even though the actual aggregate CPU/Memory utilization of the cluster is hovering around 10%.
Rightsizing at the Pod Level
The solution is Rightsizing, but applied at the micro-level. You must tightly align the "Requests" with actual historical usage.
Utilize tools like the Vertical Pod Autoscaler (VPA) in recommendation mode, or Kubecost's rightsizing dashboards. These tools analyze the actual memory and CPU consumption of a pod over a 7-day period and provide the exact mathematical recommendation for adjusting the Requests down. Lowering Requests allows the scheduler to pack pods much more densely onto the nodes, allowing you to shrink the overall size of the cluster.
Node Autoscaling (Cluster Autoscaler vs. Karpenter)
Once the pods are packed densely, the cluster must dynamically scale the underlying EC2 nodes based on demand.
Cluster Autoscaler: The legacy method. It watches for pods that cannot be scheduled due to lack of resources and triggers an AWS Auto Scaling Group to spin up a new node. It is functional but slow and inflexible.
Karpenter: The modern, FinOps-optimized standard for AWS EKS. Karpenter bypasses Auto Scaling Groups entirely. When a pod needs to be scheduled, Karpenter looks at the exact resource requirements of that specific pod, queries the AWS EC2 API, and spins up the absolute cheapest, most perfectly sized instance type (e.g., an ARM-based Graviton instance) to handle that specific workload in milliseconds. Karpenter can yield massive cost savings by continuously consolidating pods and terminating underutilized nodes.
Spot Instances in Kubernetes
Because Kubernetes is inherently designed to handle pod failure, it is the perfect environment for Spot Instances.
Configure Karpenter to aggressively utilize Spot Instances for stateless, fault-tolerant workloads (like background workers or scalable web frontends). By running these workloads on Spot rather than On-Demand instances, you can slash the compute cost of the cluster by up to 80-90% with minimal risk to availability.
Key Takeaway
Kubernetes requires its own specific FinOps discipline. Traditional cloud billing cannot penetrate the cluster. You must deploy tools like Kubecost to attribute costs to namespaces and deployments. The fastest path to cost reduction is aggressively right-sizing Pod "Requests" to allow denser scheduling, and migrating node provisioning from the legacy Cluster Autoscaler to Karpenter to enable dynamic, cost-optimized node selection and aggressive Spot Instance utilization.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.