The Loss of the SSH Key
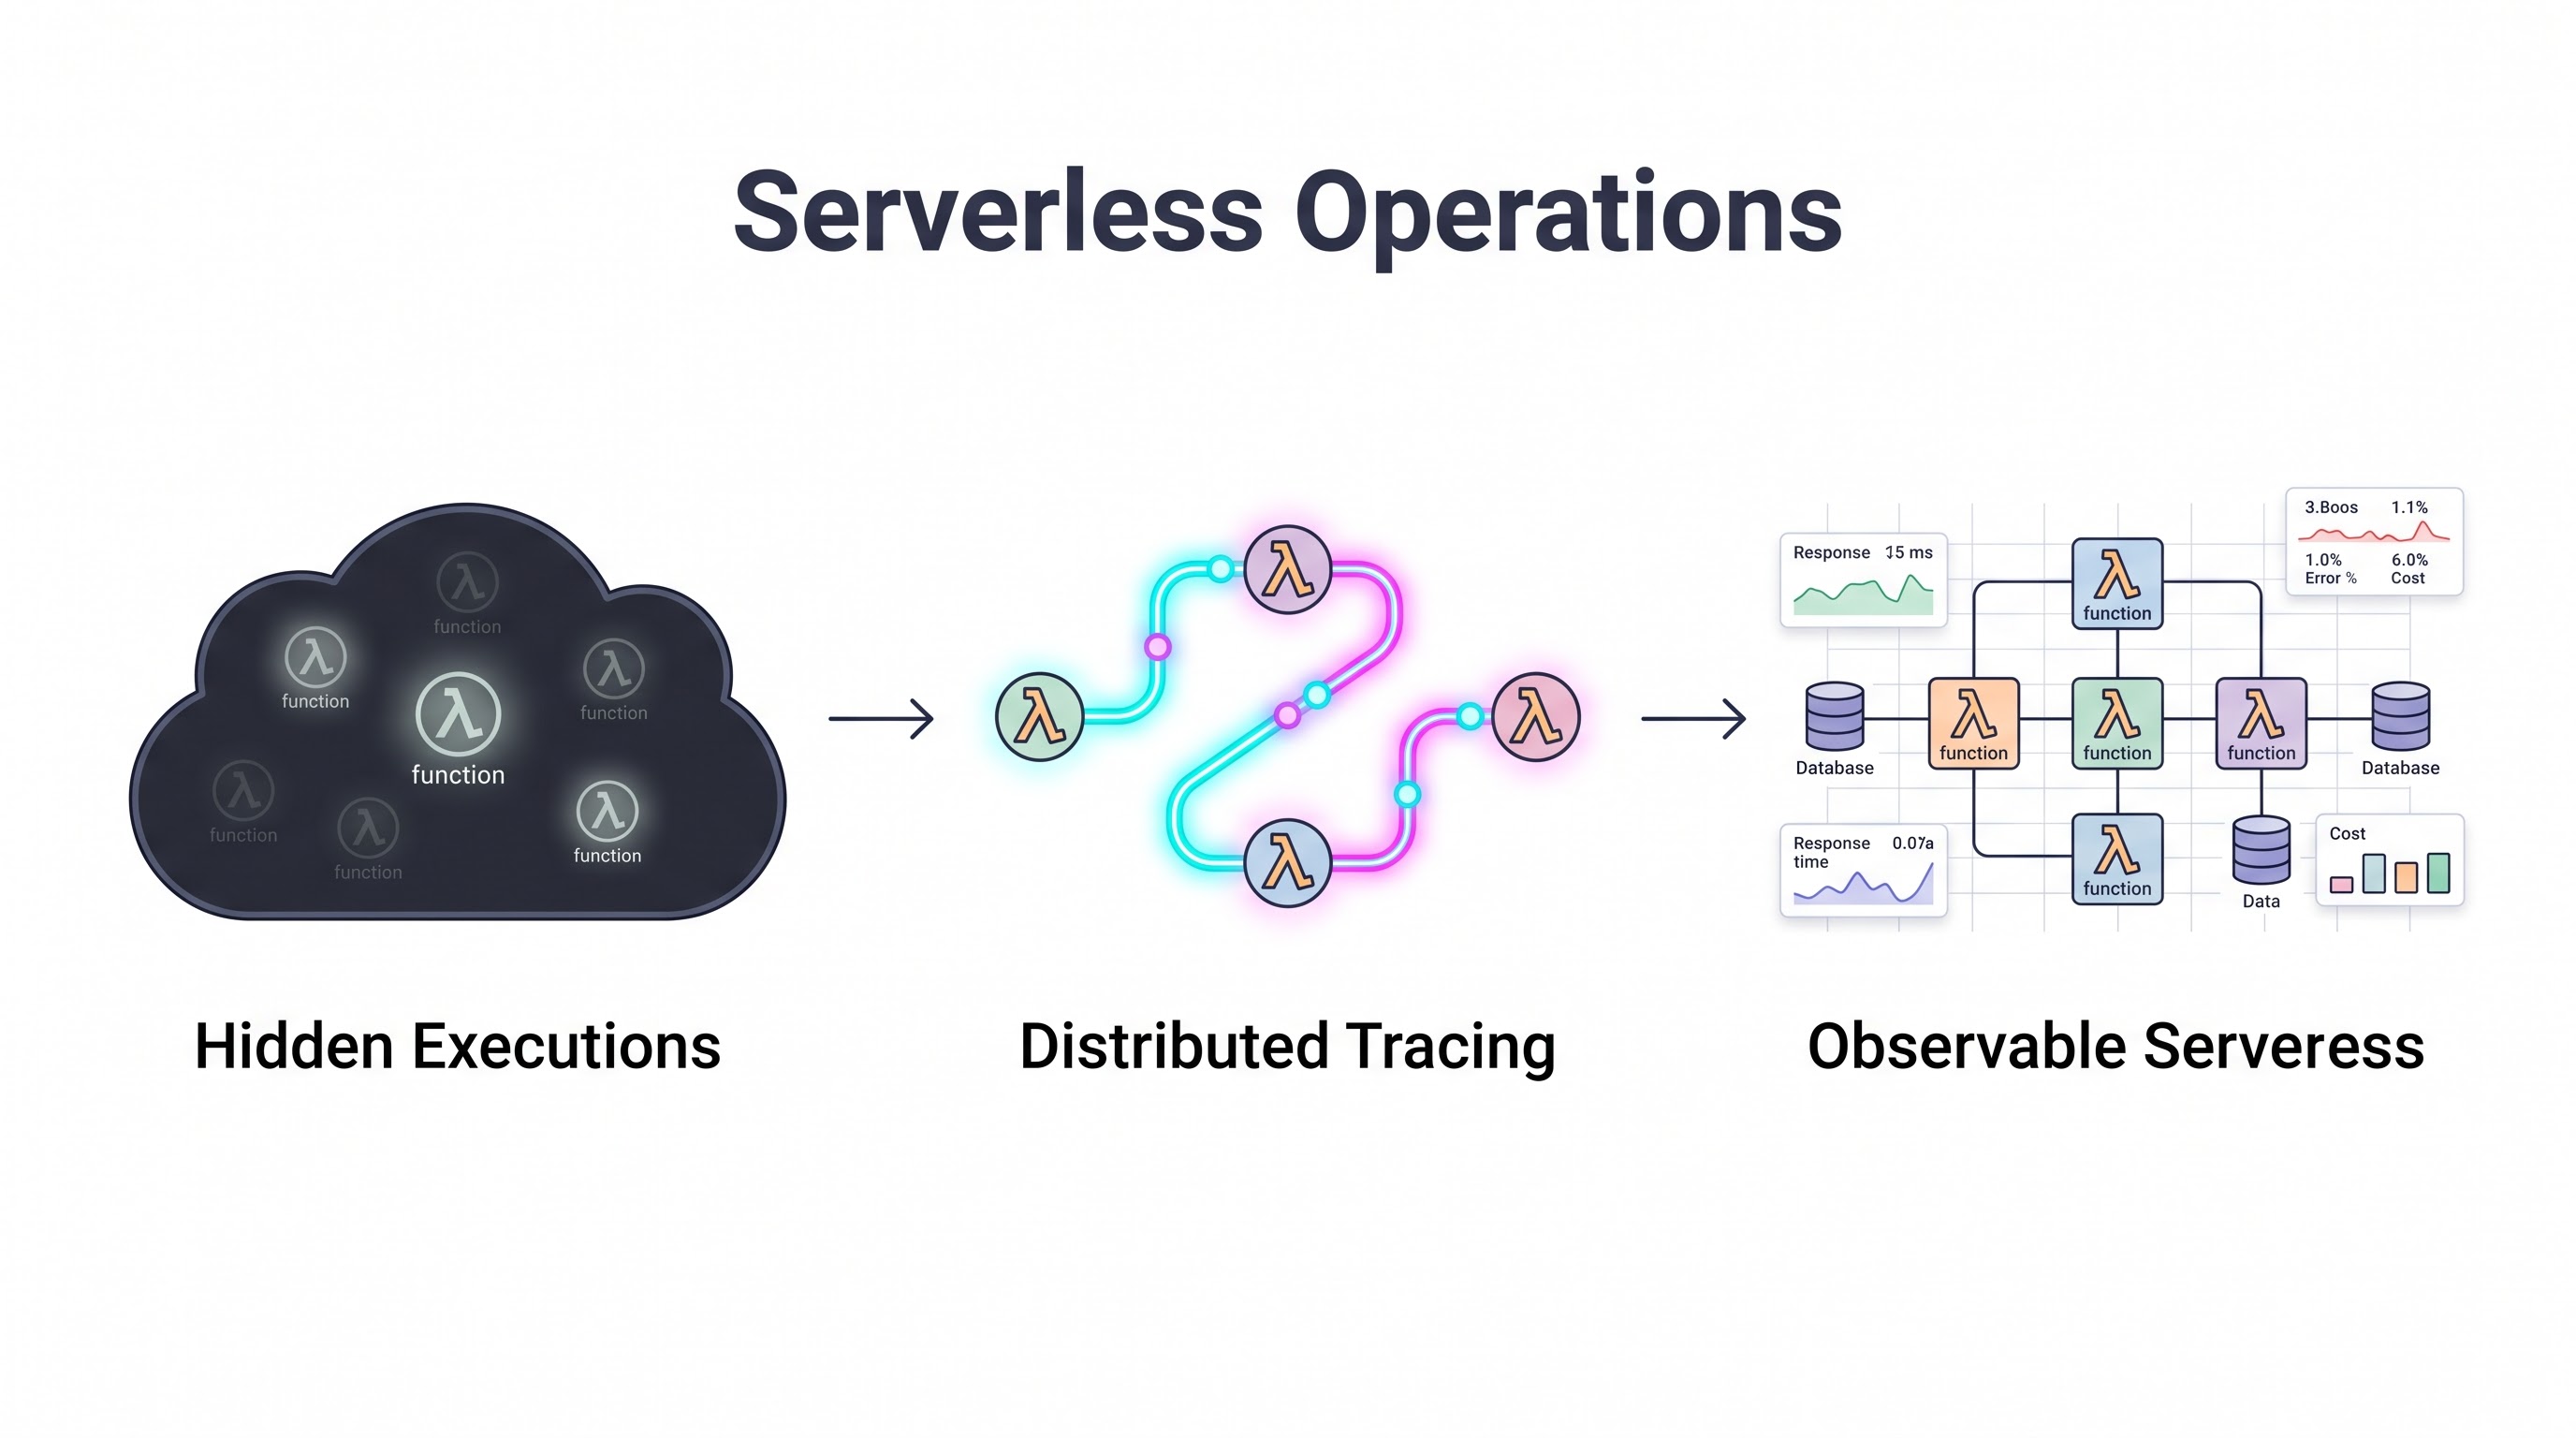
When transitioning from virtual machines to serverless architectures (AWS Lambda, Azure Functions), the most jarring cultural shift for an operations engineer is the loss of the SSH key. When a monolithic application misbehaves, the instinct is to log into the server, run top, check the memory utilization, and tail the local log files. In a serverless environment, there is no server to log into. The underlying infrastructure is a black box managed entirely by the cloud provider.
This lack of traditional access does not mean operations disappear; it means operations must evolve. You can no longer debug the environment; you must debug the system. Serverless operations relies entirely on robust, upfront instrumentation, structured logging, and an understanding of highly distributed, asynchronous event flows.
This guide explores the specific techniques required to operate, monitor, and troubleshoot modern serverless architectures effectively.
The Absolute Necessity of Distributed Tracing
As detailed in the Observability Guide, distributed tracing is critical for microservices. For serverless, it is mandatory.
A single user action (e.g., "Upload Avatar") might trigger an API Gateway, which invokes a Lambda function, which writes to an S3 bucket, which triggers an EventBridge rule, which invokes a second Lambda function to resize the image. If the user receives a "500 Internal Server Error," looking at raw text logs is useless. You will see thousands of disconnected log entries across multiple services.
The Solution: You must implement tracing (e.g., AWS X-Ray, Datadog APM, or OpenTelemetry). Tracing injects a unique correlation ID at the API Gateway and passes it through every subsequent service. This allows the operations engineer to view a single waterfall chart of the entire transaction, instantly identifying that the failure occurred because the second Lambda function lacked the IAM permissions to write the resized image back to S3.
Mitigating the Cold Start Reality
The most common operational complaint in serverless is the "Cold Start." When a Lambda function has not been invoked recently, the cloud provider spins down the execution environment to save resources. When a new request arrives, the provider must allocate compute, download the code, and initialize the runtime (e.g., spinning up the Java Virtual Machine) before executing the code. This initialization can add seconds of latency to the request.
Operational Mitigations:
Language Choice: Heavy runtimes (Java, .NET) have significantly longer cold starts than lightweight runtimes (Node.js, Python, Go).
Minimize Deployment Package: Only include the dependencies the function actually needs. A massive deployment package takes longer to download and initialize.
Provisioned Concurrency: If latency is critical (e.g., a synchronous customer-facing API), enable Provisioned Concurrency. This tells AWS to keep a specified number of execution environments initialized and warm at all times. Note: This incurs an hourly cost, effectively nullifying the "pay-per-request" economic benefit of serverless for those specific instances.
Debugging Event-Driven Architectures (SQS/EventBridge)
Serverless heavily utilizes asynchronous, event-driven architectures. A function doesn't wait for a response; it drops a message on a queue (SQS) or an event bus (EventBridge) and terminates.
Debugging asynchronous flows is notoriously difficult because errors do not immediately bubble up to the user. If a downstream function fails to process a queue message, the user never sees an error, but the data is silently lost.
The Importance of Dead-Letter Queues (DLQs)
The fundamental operational safety net for event-driven architectures is the Dead-Letter Queue (DLQ).
When a Lambda function pulls a message from an SQS queue and fails to process it (due to a bug or a downstream database timeout), the message goes back onto the queue. It will be retried. If it fails repeatedly (e.g., 3 times), the message must not be deleted. It must be automatically routed to a DLQ.
Operations Workflow:
Set up CloudWatch Alarms to trigger a PagerDuty alert anytime the
NumberOfMessagesSentmetric on a DLQ is greater than zero.The operations engineer investigates the DLQ, identifies the poison pill message, and analyzes the associated trace to find the bug.
The development team deploys a code fix.
The operations engineer "drives" the messages from the DLQ back into the primary queue to be reprocessed successfully, ensuring zero data loss.
The "Local Testing" Fallacy
A common friction point in serverless operations is the difficulty of local testing. Developers often attempt to run complex serverless emulators on their laptops (e.g., LocalStack). While useful for basic unit testing, these emulators cannot accurately replicate complex cloud IAM permissions, API Gateway routing, or obscure DynamoDB behaviors.
The Cloud-Native Approach: Developers should test in the cloud. Provide every developer with their own isolated AWS sandbox account. Utilizing rapid deployment tools (like AWS SAM or the Serverless Framework), developers push their code to actual cloud infrastructure in seconds, ensuring that when the code works in the "Dev" account, it will behave identically in the "Prod" account.
Integrating Security Operations
As detailed in the Serverless Security Guide, operations teams must monitor for specific attack vectors. Ensure API Gateways have strict rate limits configured to prevent "Denial of Wallet" attacks. Utilize tools like GuardDuty to monitor the API calls made by the Lambda functions to detect compromised execution roles attempting lateral movement.
Key Takeaway
Operating serverless architectures requires abandoning the concept of the "server." You cannot SSH in to fix a problem. Operations must rely entirely on deep instrumentation. Distributed tracing is mandatory to visualize request flows across asynchronous boundaries. Master the implementation of Dead-Letter Queues to prevent silent data loss, and utilize centralized logging platforms to query the massive volume of structured telemetry data generated by highly ephemeral functions.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.