The Economics of Ephemeral Compute
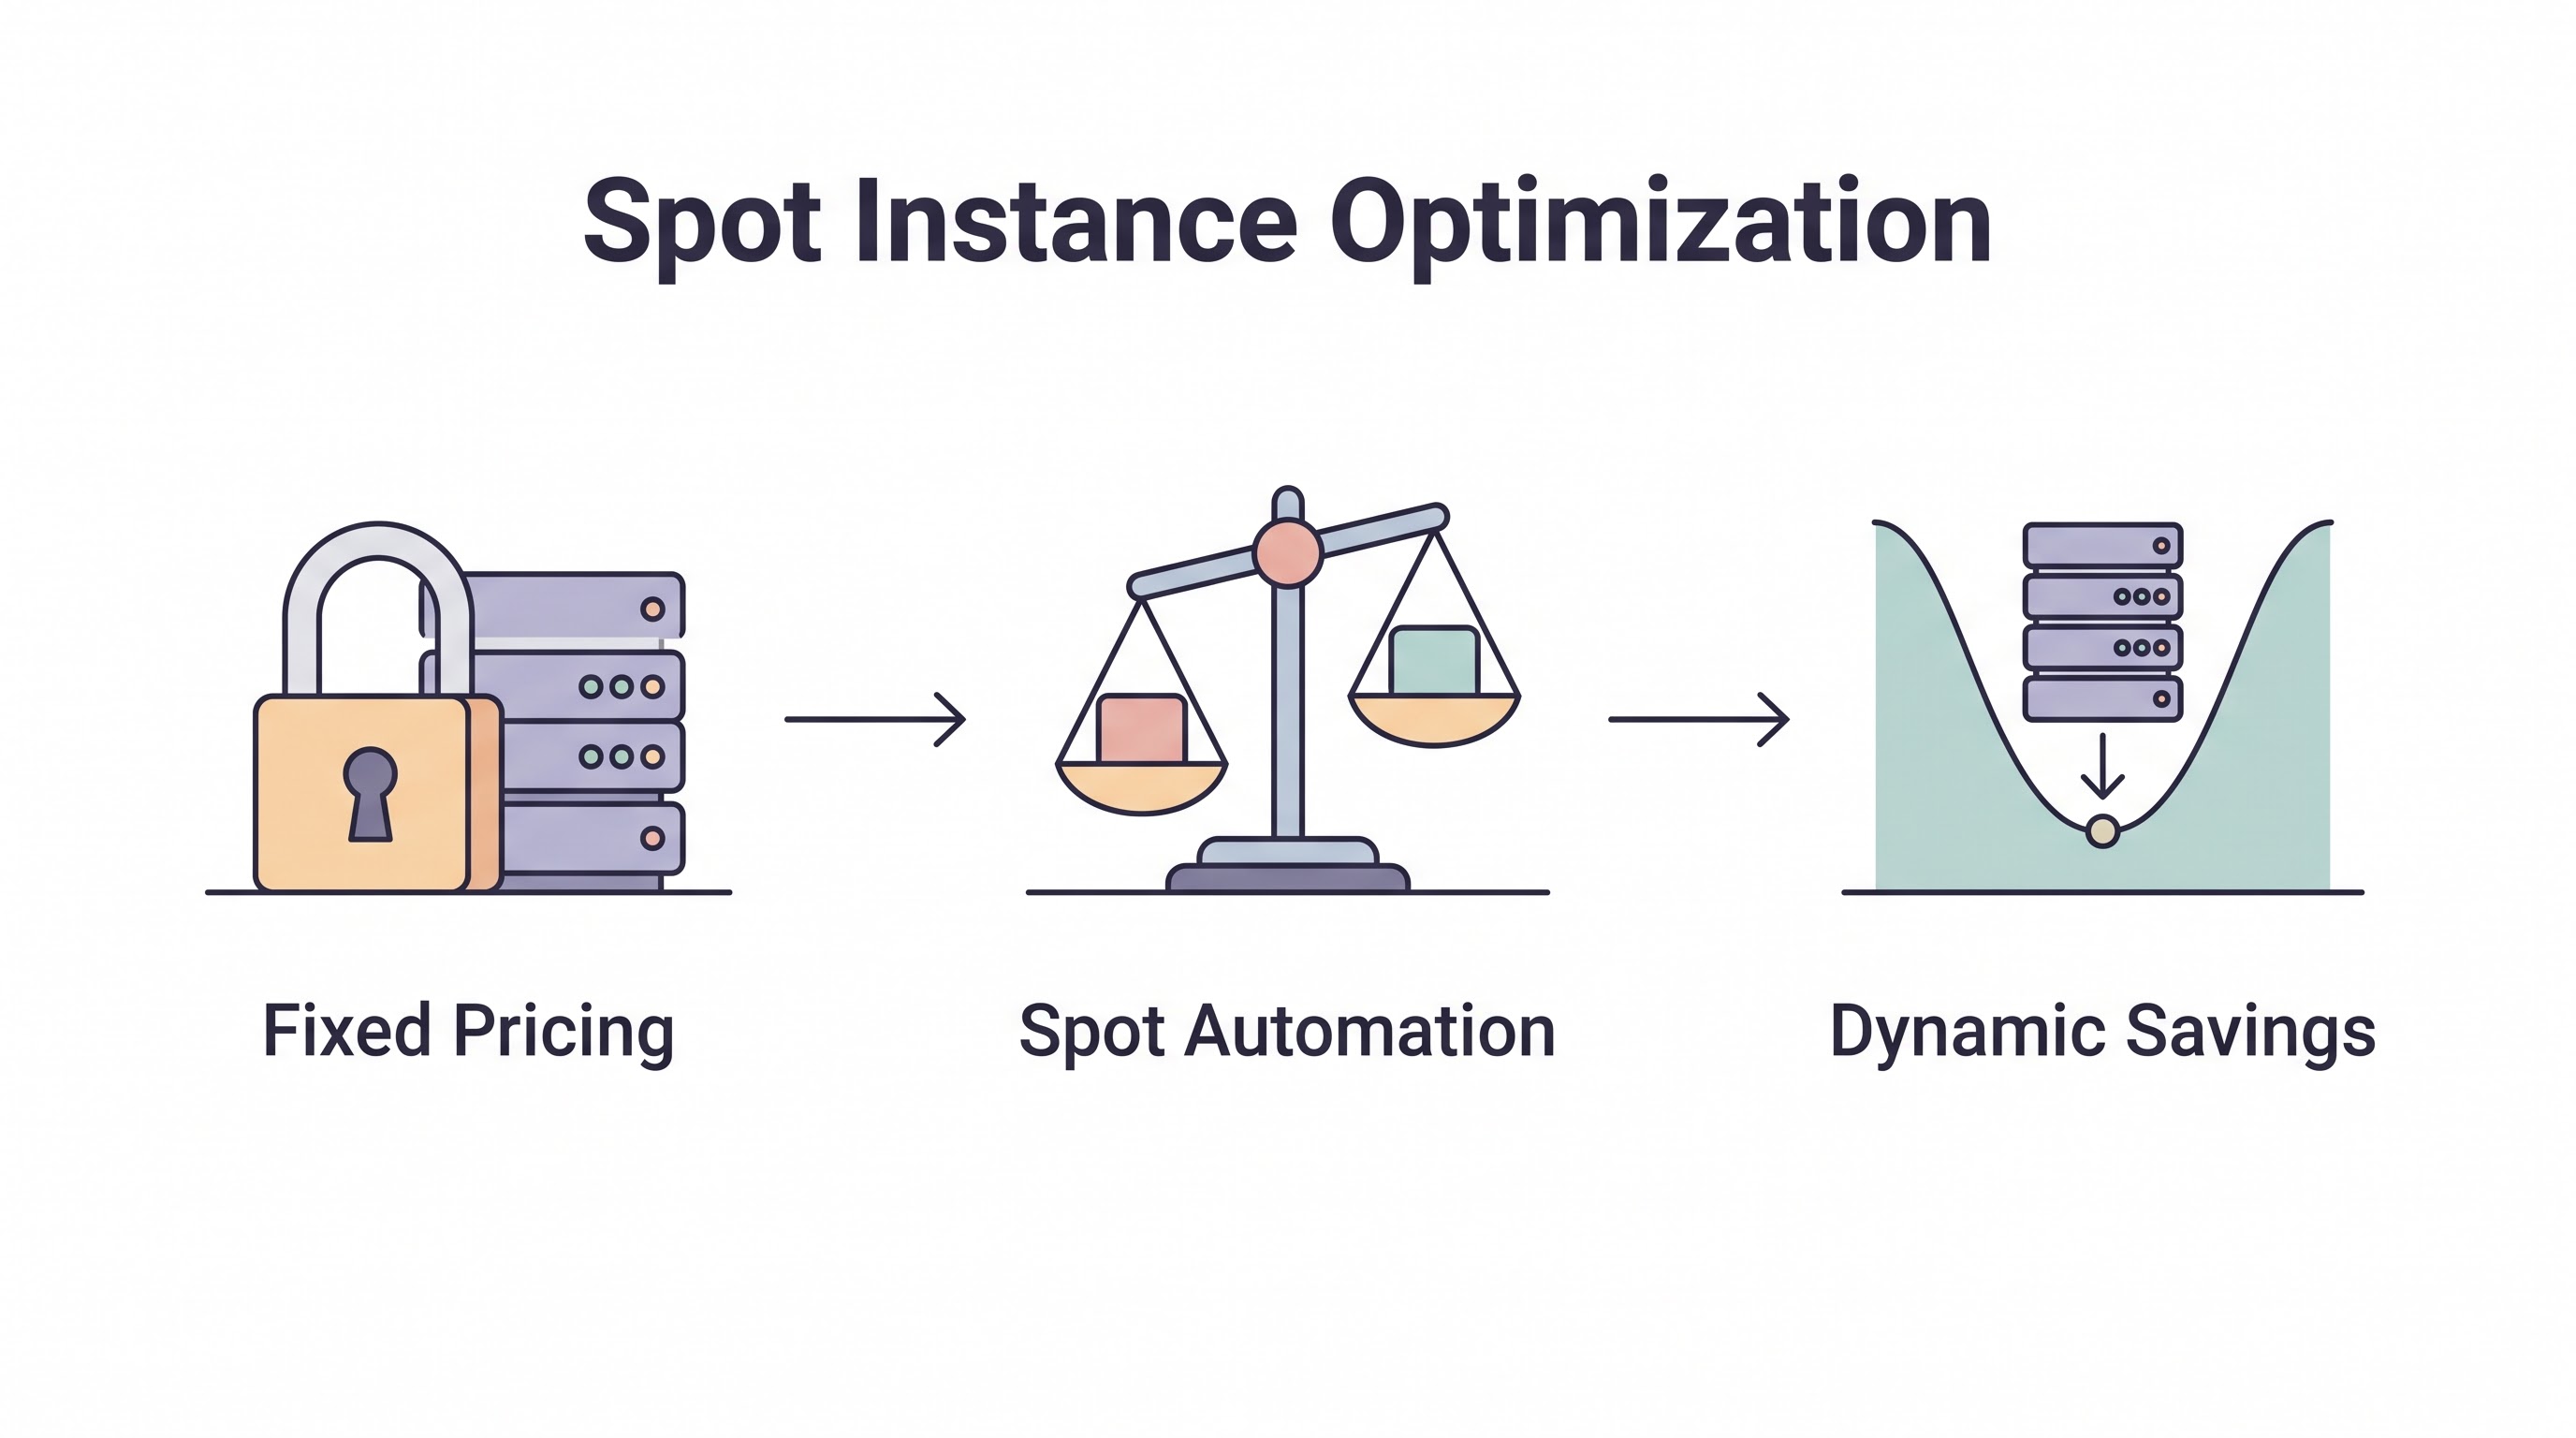
Cloud providers build massive data centers to ensure they always have sufficient capacity to handle peak customer demand. Consequently, they possess vast amounts of idle compute power at any given moment. To monetize this unused capacity, AWS, Azure, and GCP offer it at steeply discounted rates—often up to 90% off standard On-Demand prices.
This is the domain of Spot Instances (AWS/Azure) and Preemptible VMs (GCP). The catch? The cloud provider can reclaim this capacity at any time, usually with only a few minutes' notice, if a full-paying customer requests it.
For organizations willing to engineer for volatility, Spot instances represent the single largest compute optimization lever available, dwarfing the savings offered by Reserved Instances or Savings Plans. This guide outlines the architectural patterns and automation necessary to confidently run production workloads on ephemeral compute.
Understanding Spot and Preemptible Instances
While the terminology differs, the underlying mechanics are similar across the major providers.
AWS Spot Instances: Offers a 2-minute interruption warning. Prices fluctuate based on supply and demand within a specific Availability Zone and instance pool.
GCP Preemptible VMs (and Spot VMs): Preemptible VMs last a maximum of 24 hours and provide a 30-second warning. GCP's newer Spot VMs function similarly to AWS, without the 24-hour limit.
Azure Spot Virtual Machines: Offers a 30-second warning via Azure Scheduled Events. Prices can be capped by the user or allowed to float with market rates.
The core challenge is identical: your infrastructure will disappear out from under your application. You must design systems that expect and gracefully handle sudden termination.
Identifying Spot-Ready Workloads
Not all applications can survive Spot interruptions. Trying to force a legacy, stateful monolith onto Spot instances is a recipe for catastrophic downtime. You must categorize workloads based on their tolerance for interruption.
Ideal Spot Workloads:
Batch Processing & Data Analytics: Hadoop clusters, Apache Spark jobs, and media rendering pipelines. If a node dies, the master node simply reassigns the chunk of work to a new node.
CI/CD Pipelines: Jenkins build agents or GitLab runners. If a build fails due to an interruption, the pipeline automatically restarts it.
Stateless Web Services: Microservices that store session data in external databases (like Redis or DynamoDB). If a web node dies, the load balancer routes traffic to surviving nodes without user disruption.
Machine Learning Training: Training jobs that frequently checkpoint their state to S3/GCS. Upon interruption, a new instance resumes training from the last checkpoint.
Workloads to Avoid:
Stateful Databases: Running the primary node of an RDS or Cassandra cluster on Spot is highly dangerous. Data corruption and severe downtime are likely.
Legacy Monoliths: Applications that take 15 minutes to boot up cannot survive a 2-minute interruption window.
Architectural Patterns for Spot Resilience
To run Spot instances reliably, you must implement specific architectural patterns that mitigate the risk of sudden capacity loss.
1. Diversification is Mandatory
Spot capacity pools are highly specific—they are defined by Instance Type + Availability Zone (e.g., m5.large in us-east-1a). If a provider reclaims capacity, they typically reclaim an entire pool simultaneously. If your entire application runs on m5.larges in a single AZ, an interruption will cause a total outage.
The Solution: Configure your Auto Scaling Groups (ASGs) to utilize multiple instance types (e.g., m5.large, m4.large, c5.large, r5.large) across multiple Availability Zones. If AWS reclaims the m5.larges in AZ-A, your application continues running on the other instance types and in other AZs.
2. The Capacity Optimized Strategy
When configuring an AWS ASG for Spot, do not select the "Lowest Price" allocation strategy. The absolute cheapest instances are usually the ones with the least spare capacity, making them the most likely to be interrupted. Instead, use the "Capacity Optimized" strategy. AWS will provision instances from the pools with the deepest available capacity, significantly reducing your interruption rate.
Automation: Handling the Interruption
You cannot rely on manual intervention to handle a 2-minute warning. Automation must catch the signal and drain the node.
Providers expose termination notices via instance metadata APIs or EventBridge/PubSub messages. You must deploy agents (like the AWS Node Termination Handler) to monitor these endpoints. When a termination notice is detected, the automation should:
Remove the instance from the Load Balancer.
Stop sending new tasks to the instance.
Gracefully shut down running processes (saving state if necessary).
Signal the Auto Scaling Group to begin provisioning a replacement instance immediately.
Spot Instances and Kubernetes
Kubernetes and Spot instances are a perfect operational match. Kubernetes is inherently designed to maintain a desired state; if a node disappears, the control plane immediately reschedules the orphaned pods onto surviving nodes.
As detailed in the Kubernetes Cost Management Guide, utilizing Spot nodes in EKS, AKS, or GKE requires applying specific Kubernetes "Taints." Taints ensure that critical system pods (like CoreDNS or ingress controllers) are never scheduled on ephemeral Spot nodes, reserving the volatile capacity purely for resilient worker pods.
The Power of Mixed Node Pools
The most mature strategy is the Mixed Node Pool approach. You do not run an entire service on Spot instances. Instead, you run the baseline capacity (the minimum required to keep the service functional) on On-Demand instances or Reserved Instances. You then configure the autoscaler to provision all burst capacity (handling traffic spikes) using Spot instances.
This hybrid approach guarantees that the service will never go offline, even in the event of a massive Spot capacity reclamation, while still capturing 70-90% savings on the majority of your compute footprint.
Risk Management and Bidding Strategies
Historically, Spot instances required complex bidding strategies. Today, the major providers have simplified the model. You pay the market price up to your defined maximum (usually the On-Demand price). Complex bidding is an anti-pattern; it rarely yields better availability.
The ultimate risk mitigation is utilizing dedicated FinOps automation tools. Advanced platforms monitor the global Spot market, predicting interruptions based on historical data. They can proactively cordon and drain a Spot instance and replace it with a more stable instance type before the cloud provider issues the termination warning, effectively providing an On-Demand SLA at Spot pricing.
Key Takeaway
Spot instances offer staggering discounts, but they require engineering investment to utilize safely. Never run stateful databases on Spot. For stateless web services, CI/CD, and batch processing, Spot is highly recommended. Success requires diversifying across instance types and availability zones, utilizing capacity-optimized allocation strategies, and implementing automated node termination handlers to gracefully drain workloads before the instance vanishes.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.