Kubernetes is widely celebrated as the ultimate solution for container orchestration, promising unparalleled scalability and operational resilience. However, for organizations migrating from traditional monolithic architectures, Kubernetes often introduces a shocking financial reality: a massive, inexplicable spike in their cloud infrastructure bill.
This "Kubernetes Tax" isn't an inherent flaw in the orchestrator itself; rather, it is almost exclusively the result of poor bin packing. Datadog's extensive 2023 report on container usage revealed a staggering statistic: the average Kubernetes cluster utilizes less than 40% of its provisioned CPU and Memory. In enterprise environments, this translates to millions of dollars spent annually on AWS EC2 instances that are literally doing nothing.
In this 2,500+ word deep-dive, we will explore the science and art of Kubernetes bin packing. We will move beyond the basics of defining requests and limits, venturing into the mathematical realities of cluster fragmentation, the critical role of the Kubernetes Scheduler, the necessity of the Descheduler, and how next-generation auto-provisioners like AWS Karpenter are fundamentally changing the FinOps landscape.
Section 1: The Physics of Cluster Fragmentation
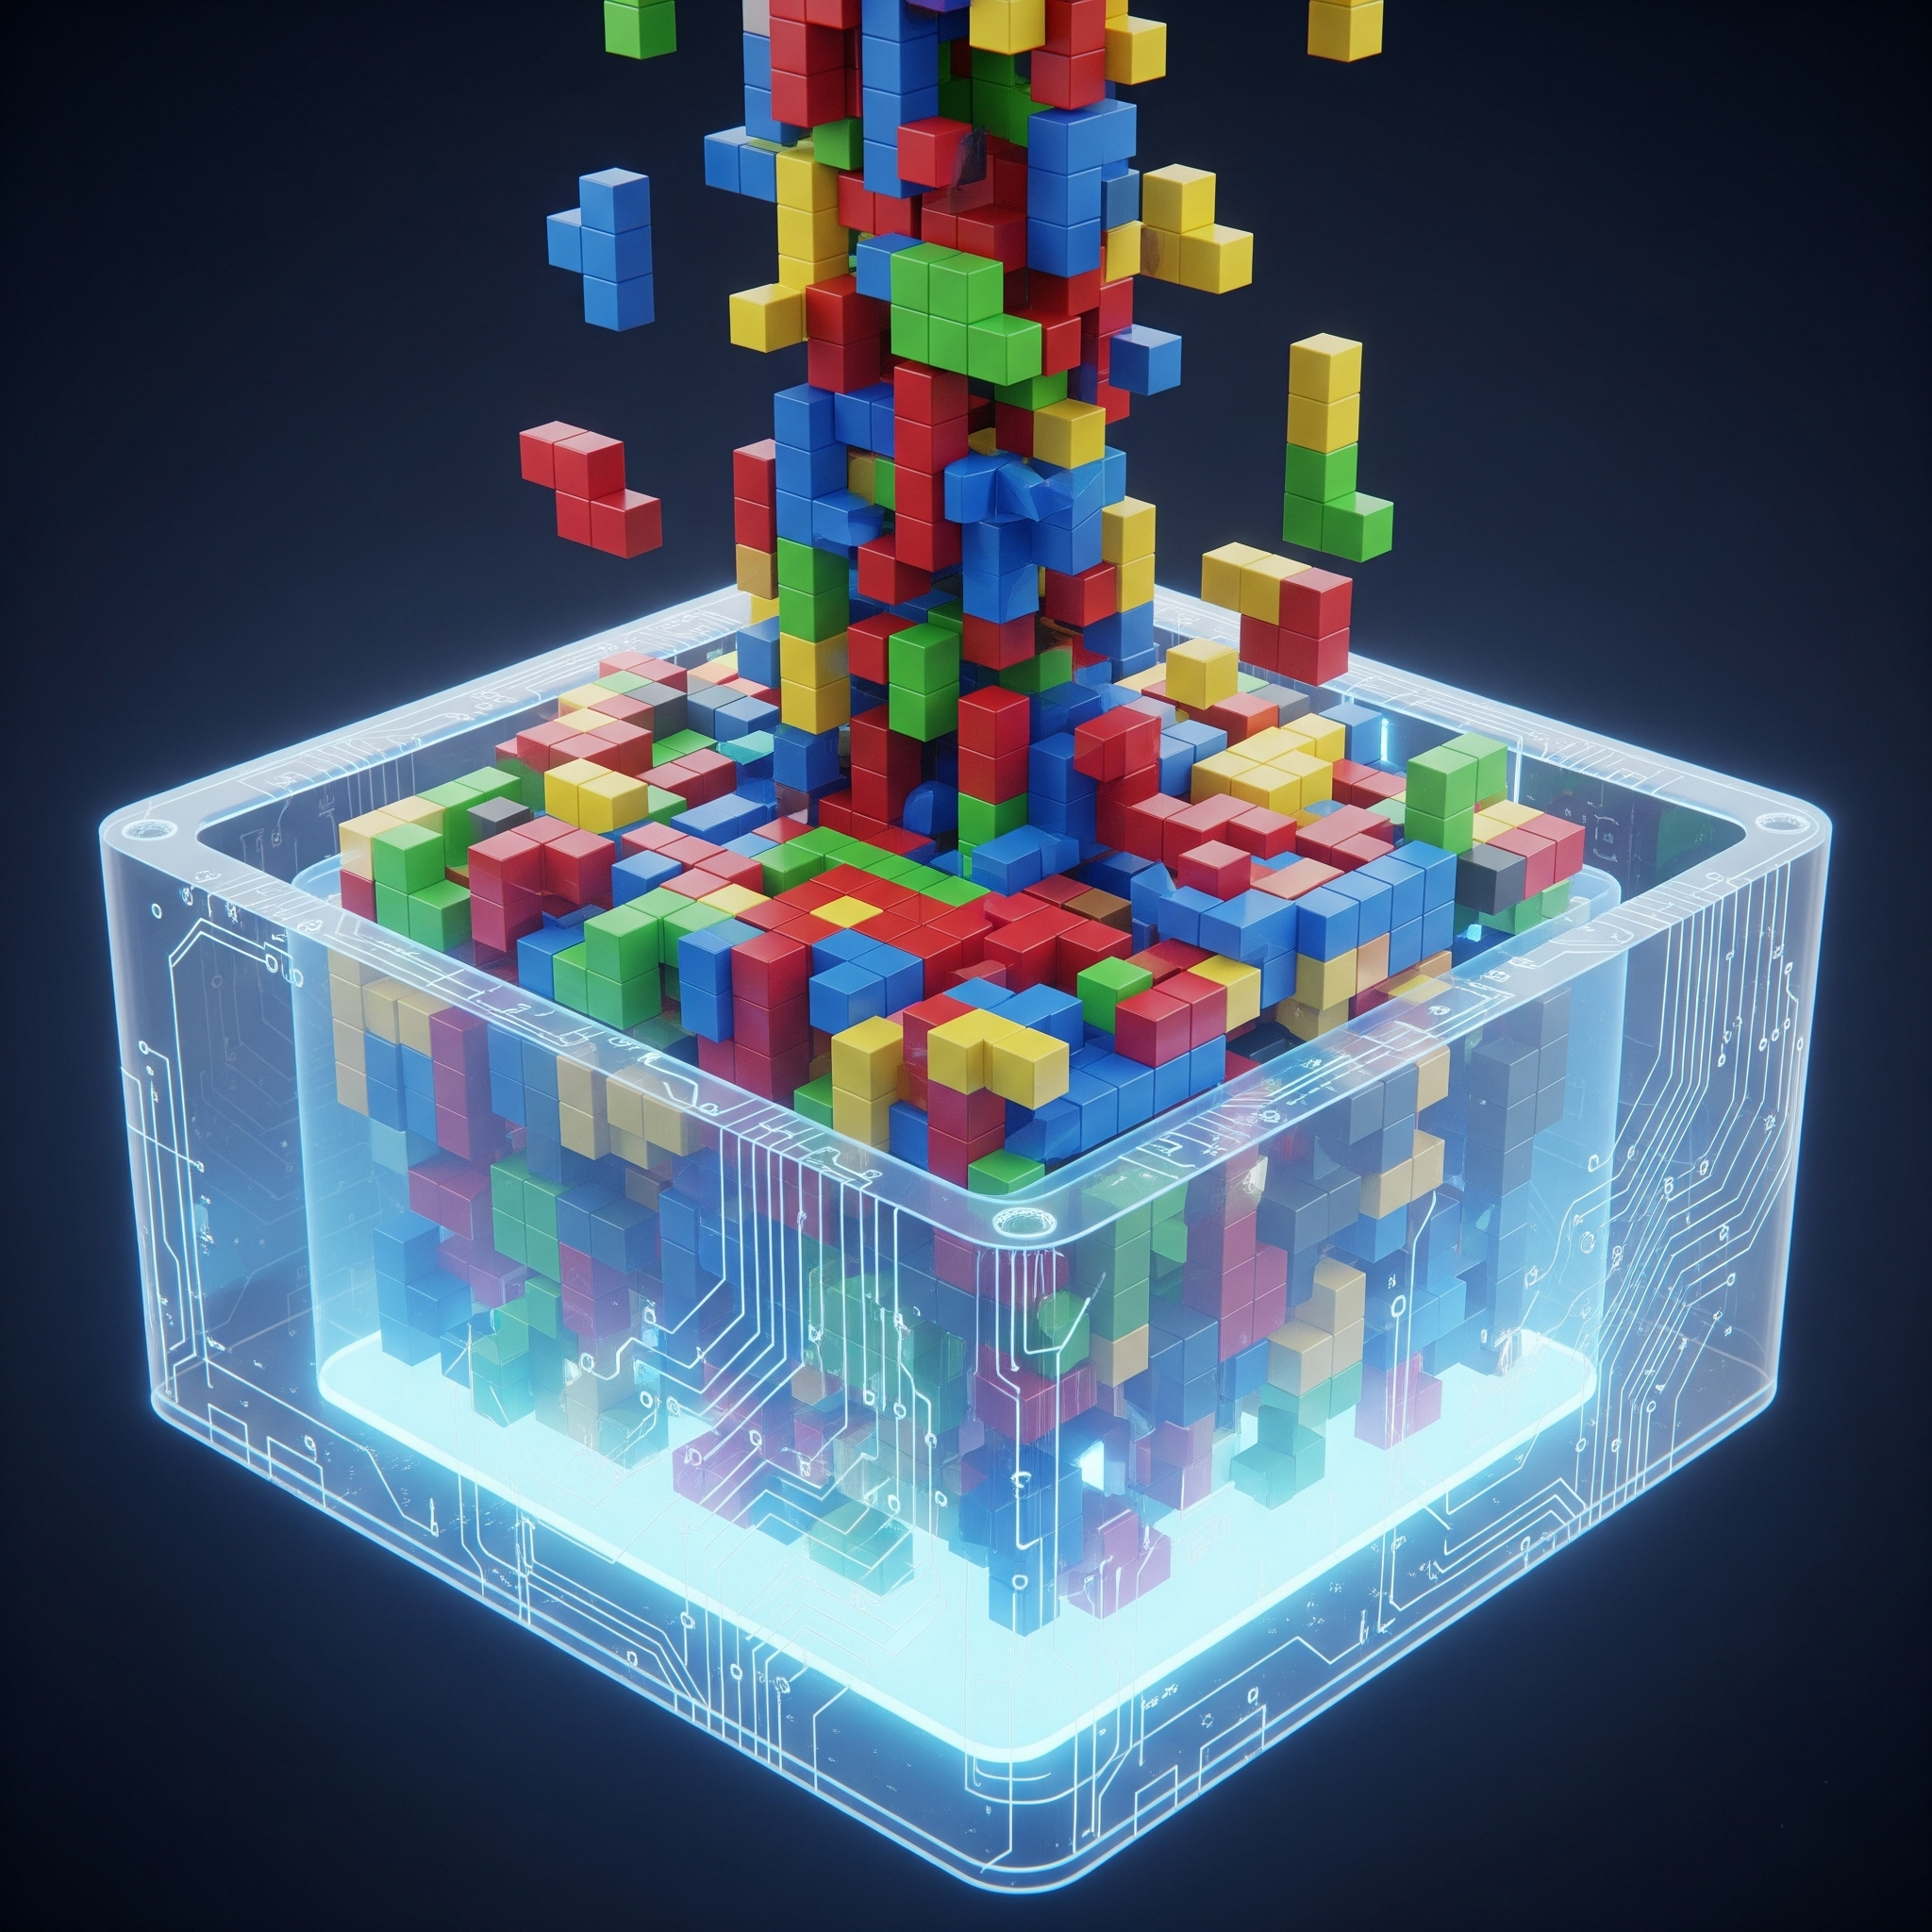
To understand bin packing, you must visualize a Kubernetes cluster not as a single supercomputer, but as a collection of rigid, physical boxes (the Nodes). Your applications (the Pods) are irregularly shaped items that must be crammed into those boxes.
The goal of bin packing is to fill those boxes as close to 100% capacity as possible before provisioning a new box. However, two primary factors cause severe fragmentation, leaving massive empty spaces (wasted compute) inside the boxes.
1. The Resource Request Disconnect
The Kubernetes Scheduler makes placement decisions based entirely on Resource Requests, not actual utilization. If a developer deploys a Java Spring Boot application and sets requests.cpu: "4" (4 CPU cores), the scheduler subtracts 4 cores from the target node's allocatable capacity.
If that Java application only actually consumes 0.2 cores during normal operations, the node still considers those remaining 3.8 cores "reserved." No other pods can be scheduled into that reserved space, even though the physical CPU is essentially idle. This is the most common cause of wasted cloud spend: developers over-provisioning requests out of an abundance of caution, terrified of CPU throttling.
2. The Tetris Problem (Asymmetrical Sizing)
Even if developers request exactly what they need, fragmentation still occurs due to asymmetrical pod sizes. Imagine a node with 8 allocatable CPUs. You schedule two pods, each requesting 3 CPUs. The node now has 2 CPUs remaining.
If your next deployment consists entirely of pods requesting 3 CPUs, none of them can fit on that node. The Kubernetes Cluster Autoscaler will spin up a brand new EC2 instance to house the new pod, leaving the 2 CPUs on the first node permanently empty and wasted. Across a 500-node cluster, these "leftover" fragments accumulate into massive financial losses.
The FinOps Blind Spot: Traditional cloud billing tools like AWS Cost Explorer cannot see inside a Kubernetes cluster; they only see the EC2 instances. To actually identify which teams are causing fragmentation through over-provisioned requests, you need specialized tooling. Read our comprehensive OpenCost vs Kubecost Comparison to learn how to implement pod-level financial attribution.
Section 2: Mastering the Foundation: Requests, Limits, and VPA
You cannot solve cluster fragmentation without first fixing the accuracy of your pod resource definitions. Bin packing algorithms are only as good as the data they are fed.
The Strict Request vs Limit Paradigm
A rigorous engineering culture must enforce the following rules:
Requests = Baseline Reality: Requests should be set to the average steady-state consumption of the application, not the absolute peak. This allows the scheduler to pack pods tightly.
Limits = Safety Net: Limits should be set to protect the node from a memory leak or a runaway process.
Burstable QoS: By setting limits significantly higher than requests, you create a "Burstable" Quality of Service (QoS) class. Because the node's physical CPU is rarely fully utilized (due to varying traffic spikes across different pods), setting low requests allows the scheduler to overcommit the physical hardware safely, relying on Linux cgroups to throttle pods only if the physical CPU actually reaches 100%.
Automating Accuracy with Vertical Pod Autoscaler (VPA)
Expecting developers to manually guess their exact CPU and Memory requirements is a recipe for failure. To achieve elite bin packing, you must deploy the Vertical Pod Autoscaler (VPA).
The VPA continuously analyzes the historical CPU and memory utilization of your pods. In "Recommendation" mode, it simply outputs the mathematically optimal request sizes. In "Auto" mode, it will actually evict and restart your pods with the corrected, highly-optimized resource requests.
apiVersion: autoscaling.k8s.io/v1
kind: VerticalPodAutoscaler
metadata:
  name: payment-service-vpa
spec:
  targetRef:
    apiVersion: "apps/v1"
    kind:       Deployment
    name:       payment-service
  updatePolicy:
    updateMode: "Off" # Set to 'Auto' when confident
By forcing all deployments to adhere to VPA recommendations, you eliminate the human error of over-provisioning, immediately freeing up "reserved" space on your nodes and allowing the cluster to scale down.
Section 3: Forcing Tight Packing via the Scheduler
Once your pod sizes are mathematically accurate, you must instruct the Kubernetes Scheduler to pack them tightly. By default, the kube-scheduler actually tries to do the exact opposite: it prefers to spread pods evenly across all available nodes to maximize fault tolerance. This behavior (controlled by the NodeResourcesLeastAllocated scoring plugin) is terrible for FinOps because it keeps all nodes partially full, preventing the Cluster Autoscaler from terminating any of them.
Configuring MostAllocated
To optimize for cost, you must reconfigure the scheduler to prioritize the NodeResourcesMostAllocated plugin. This completely reverses the default behavior. When a new pod arrives, the scheduler looks for the node that is closest to being full and attempts to cram the pod in there.
This strategy deliberately leaves other nodes as empty as possible. When a node becomes completely empty, the Cluster Autoscaler terminates the underlying EC2 instance, saving you money.
Pod Affinity and Anti-Affinity
You can further guide the scheduler using topology constraints. If you have microservices that communicate heavily over the network, using podAffinity forces the scheduler to pack them onto the same physical node. This not only tightly packs the node but also completely eliminates cross-AZ data transfer fees.
Are You Paying the Cross-AZ Tax?
If your Kubernetes pods are constantly communicating across Availability Zones, your AWS bill is likely bleeding money via NAT Gateway and inter-AZ data charges. Check out our guide on Fixing Expensive NAT Gateways to understand how VPC architecture impacts your Kubernetes costs.
Section 4: The Necessity of Continuous Descheduling
A Kubernetes cluster is highly dynamic. Over weeks of deployments, rolling updates, and horizontal scaling events, a cluster that was initially perfectly bin-packed will slowly decay into extreme fragmentation. Nodes will be left with tiny pockets of available CPU that cannot fit any new workloads.
The standard Kubernetes scheduler is a one-way street. It places pods, but it never moves them after they are running, even if a much better node configuration becomes available.
Enter the Descheduler
To maintain high utilization, you must run the Kubernetes Descheduler. The Descheduler is a background process that continuously evaluates the state of the cluster against your desired bin-packing policies. If it finds a node that is severely underutilized (e.g., only 15% full), it will actively evict the pods running on that node.
Because these pods belong to ReplicaSets, they are immediately recreated. The standard scheduler (configured for MostAllocated) will then pack these newly created pods onto other, fuller nodes. This completely empties the underutilized node, allowing the Cluster Autoscaler to terminate it.
# Descheduler Policy Example
apiVersion: "descheduler/v1alpha1"
kind: "DeschedulerPolicy"
strategies:
  LowNodeUtilization:
    enabled: true
    params:
      nodeResourceUtilizationThresholds:
        thresholds:
          "cpu" : 20
          "memory": 20
        targetThresholds:
          "cpu" : 50
          "memory": 50
By running the Descheduler as a nightly CronJob, you effectively run an automated disk-defragmentation routine on your cloud compute, ensuring your cluster begins every morning tightly packed and financially optimized.
Section 5: The Revolution: AWS Karpenter
Everything discussed above relies on the standard Kubernetes Cluster Autoscaler, a tool that was designed years ago and suffers from a fundamental limitation: it relies on static AWS Auto Scaling Groups (ASGs). If your ASG is configured to use m5.xlarge instances, the Cluster Autoscaler can only ever add more m5.xlarge instances, regardless of the actual shapes of the pending pods.
This brings us back to the Tetris problem. If you need to schedule a massive ML inference pod requiring 16 CPUs, but your ASG only provides 4-CPU nodes, the pod will stay in a Pending state forever. You are forced to create dozens of distinct ASGs for different instance types, creating an operational nightmare.
Group-less Auto-Provisioning
AWS developed Karpenter to destroy this paradigm. Karpenter completely bypasses AWS Auto Scaling Groups. It connects directly to the EC2 Fleet API.
When a pod goes into a Pending state, Karpenter analyzes the exact CPU, memory, and GPU requirements of that specific pod (or batch of pending pods). It then evaluates the entire AWS catalog of hundreds of EC2 instance types and provisions the exact instance type that perfectly fits those pods with zero wasted space.
If you deploy 10 tiny microservices, Karpenter provisions a single
c6g.large.If you deploy a massive PostgreSQL database pod, Karpenter instantly provisions an
r6i.4xlarge.If you deploy a GPU workload, it provisions an
a10ginstance.
Karpenter acts as a dynamic, real-time bin-packer. It doesn't force pods into pre-existing boxes; it builds the perfect custom box for the pods you have right now.
Node Consolidation
Furthermore, Karpenter features native Consolidation. It continuously watches the cluster, effectively replacing the need for the external Descheduler. If it notices that the pods spread across three m5.xlarge instances could perfectly fit onto a single m5.2xlarge instance (which is cheaper than three smaller instances), Karpenter will spin up the larger instance, seamlessly migrate the pods, and terminate the three inefficient instances.
The Graviton Advantage: One of Karpenter's greatest FinOps features is its ability to seamlessly mix architectures. If your application is compiled for multi-arch, Karpenter will actively seek out cheaper ARM-based Graviton instances and prioritize them over Intel instances, securing an immediate 20% price-performance win without any configuration changes.
Conclusion: The Path to 80% Utilization
Achieving elite cloud financial efficiency on Kubernetes is not an accident; it is an engineering discipline. Moving from an industry-average 40% node utilization to a tightly packed 80% utilization requires a systematic approach across multiple layers of the stack.
Developers: Must adopt Vertical Pod Autoscaling to enforce mathematically accurate resource requests.
Schedulers: Must be tuned to prioritize
MostAllocatedscoring to cram pods tightly.Maintenance: Continuous Descheduling must be employed to fight cluster entropy.
Infrastructure: Legacy ASG-based autoscalers should be replaced with dynamic, group-less provisioners like Karpenter.
By treating bin packing not as an operational afterthought, but as a core architectural requirement, engineering teams can unlock the true promise of Kubernetes: massive, reliable scale without the crippling cloud infrastructure bills.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.