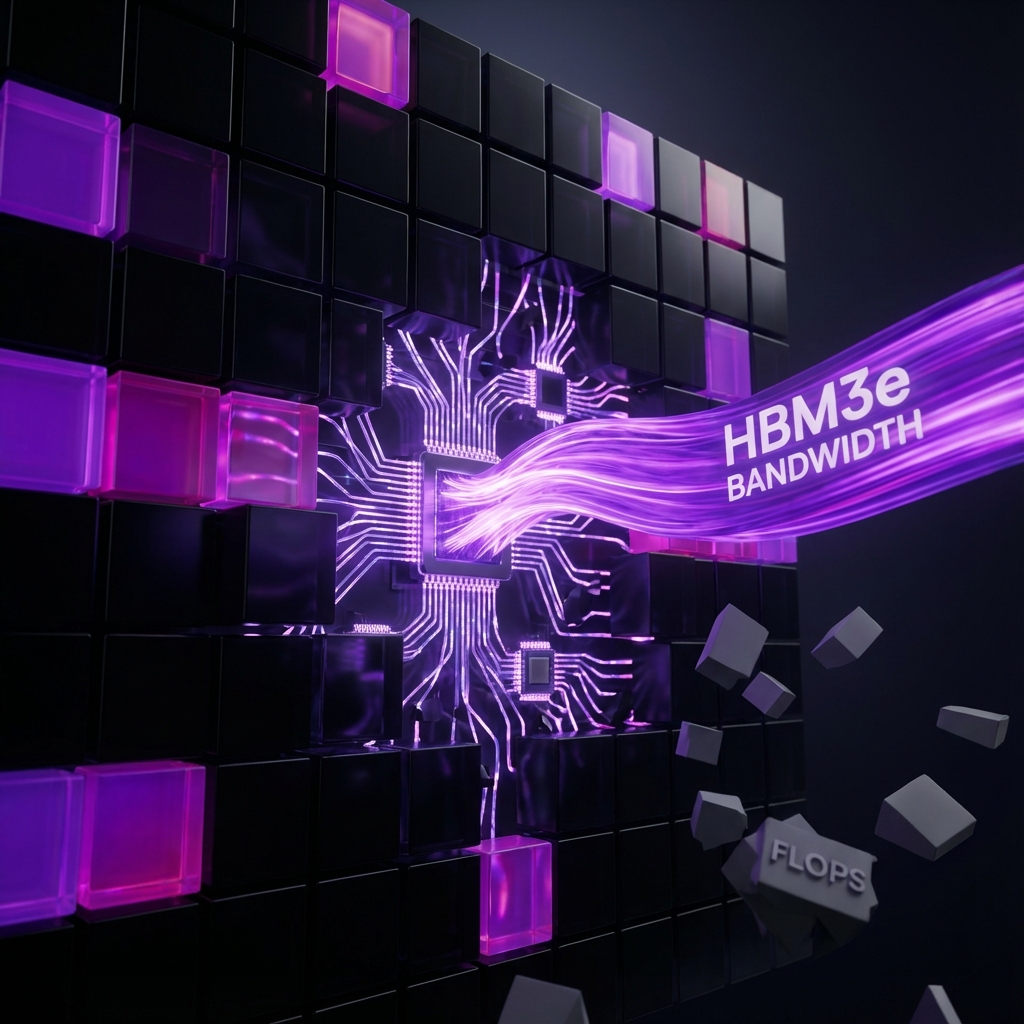
When evaluating AI hardware for a Kubernetes cluster, engineering teams often obsess over a single metric: FLOPS (Floating Point Operations Per Second). While FLOPS indicate how fast a GPU can crunch numbers, focusing solely on this metric ignores the fundamental bottleneck of modern deep learning: The Memory Wall.
The "Memory Wall" refers to the growing disparity between how fast a processor can compute data and how fast it can retrieve that data from memory. In large language model (LLM) inference, you are rarely bottlenecked by compute (FLOPS); you are almost always bottlenecked by memory bandwidth.
1. Why LLM Inference is Memory-Bound
During LLM inference—specifically the auto-regressive decoding phase where the model generates one token at a time—the GPU must load the entire multi-gigabyte model weights from High Bandwidth Memory (HBM) into its compute cores for every single token generated.
If you are running a 70-billion parameter model (roughly 140GB of weights in 16-bit precision), the GPU compute cores sit idle, waiting for those 140GBs to be transferred from the HBM. An NVIDIA H100 GPU boasts incredible FLOPS, but its true advantage for inference is its 3.35 TB/s of memory bandwidth. If you attempt to run the same model on consumer-grade GPUs with high FLOPS but low bandwidth (like the RTX 4090), the generation speed will crawl to a halt.
2. FinOps Implications of the Memory Wall
Understanding the memory wall is critical for cloud cost optimization. A common FinOps mistake is over-provisioning compute (renting expensive, high-FLOPS instances like AWS P5s) for inference workloads that only require high memory bandwidth.
To optimize costs, engineering teams must deploy memory-efficient architectures:
Quantization (INT8 and INT4): By compressing the model weights from 16-bit floats to 8-bit or 4-bit integers, you drastically reduce the amount of data that must cross the memory wall. A quantized model requires half the memory bandwidth, allowing you to run it on significantly cheaper cloud instances (like AWS G5s instead of P4s) without a perceptible loss in quality.
KV Cache Management: During generation, the model stores previous tokens in a Key-Value (KV) cache to avoid recomputing them. If this cache grows too large, it spills out of SRAM and exacerbates the memory wall. Using frameworks like vLLM with PagedAttention ensures the KV cache is managed efficiently, increasing batch sizes and maximizing GPU utilization.
3. The Hardware Horizon: SRAM vs. HBM
To defeat the memory wall, AI chip designers are moving away from traditional GPU architectures. Specialized Neural Processing Units (NPUs) like the Groq LPU or Rebellions ATOM bypass HBM entirely by placing massive amounts of ultra-fast SRAM directly on the chip next to the compute cores.
While SRAM is incredibly expensive and limits the size of the model that can fit on a single chip, it effectively eliminates the memory wall. As these ASICs become available in public clouds, FinOps teams must integrate them into their financial operations platform models, as they will radically alter the unit economics of real-time AI inference.
4. The Impact of Sparsity on the Memory Wall
One of the most promising software-hardware co-design strategies to breach the memory wall is the aggressive implementation of "Sparsity." In massive neural networks, a large percentage of the weights eventually trend toward zero during training. When performing matrix multiplications during inference, fetching these zero-value weights from High Bandwidth Memory (HBM) and multiplying them consumes massive amounts of power and time, only to result in zero. Modern architectures, such as NVIDIA's Ampere and Hopper Tensor Cores, natively support 2:4 structured sparsity. By pruning the neural network and compressing it before inference, the hardware can mathematically skip the zero-value operations entirely. This effectively doubles the memory bandwidth and compute throughput without requiring any physical changes to the silicon, providing a massive FinOps advantage for serving large language models at scale.
5. Silicon Photonics and Optical Interconnects
As traditional copper interconnects reach their physical limits for transmitting data between the GPU cores and the HBM, the industry is racing toward Silicon Photonics. Copper wires suffer from severe signal degradation and heat generation when transmitting massive bandwidths over even tiny distances on a motherboard. Silicon Photonics replaces these copper traces with microscopic lasers and fiber optics, transmitting data via light. This allows for radically higher memory bandwidth with near-zero latency and vastly reduced power consumption. For FinOps and infrastructure teams planning multi-year AI hardware budgets, tracking the commercial viability of optical interconnects is critical. Organizations that successfully transition their AI clusters to photonics-enabled architectures will shatter the memory wall, achieving unprecedented cost-per-token efficiency in their deep learning pipelines.
Conclusion
Do not buy into the FLOPS hype. When architecting an LLM inference pipeline, memory bandwidth dictates both your latency and your cloud bill. By leveraging quantization techniques and monitoring utilization via cloud cost anomaly detection, organizations can scale their AI workloads without slamming into the memory wall.
All in One Place
Atler Pilot decodes your cloud spend story by bringing monitoring, automation, and intelligent insights together for faster and better cloud operations.